




 Infrastructure Monitoring
See Every Second of Your Infrastructure’s Pulse
True real-time monitoring with per-second visibility, ML-powered anomaly detection on every metric, and AI troubleshooting that cuts MTTR by 80% - all while keeping your data sovereign and reducing costs by 90%.

Why Infrastructure Teams Choose Netdata
Built for operations teams who need instant visibility without the complexity
True Real-Time Visibility
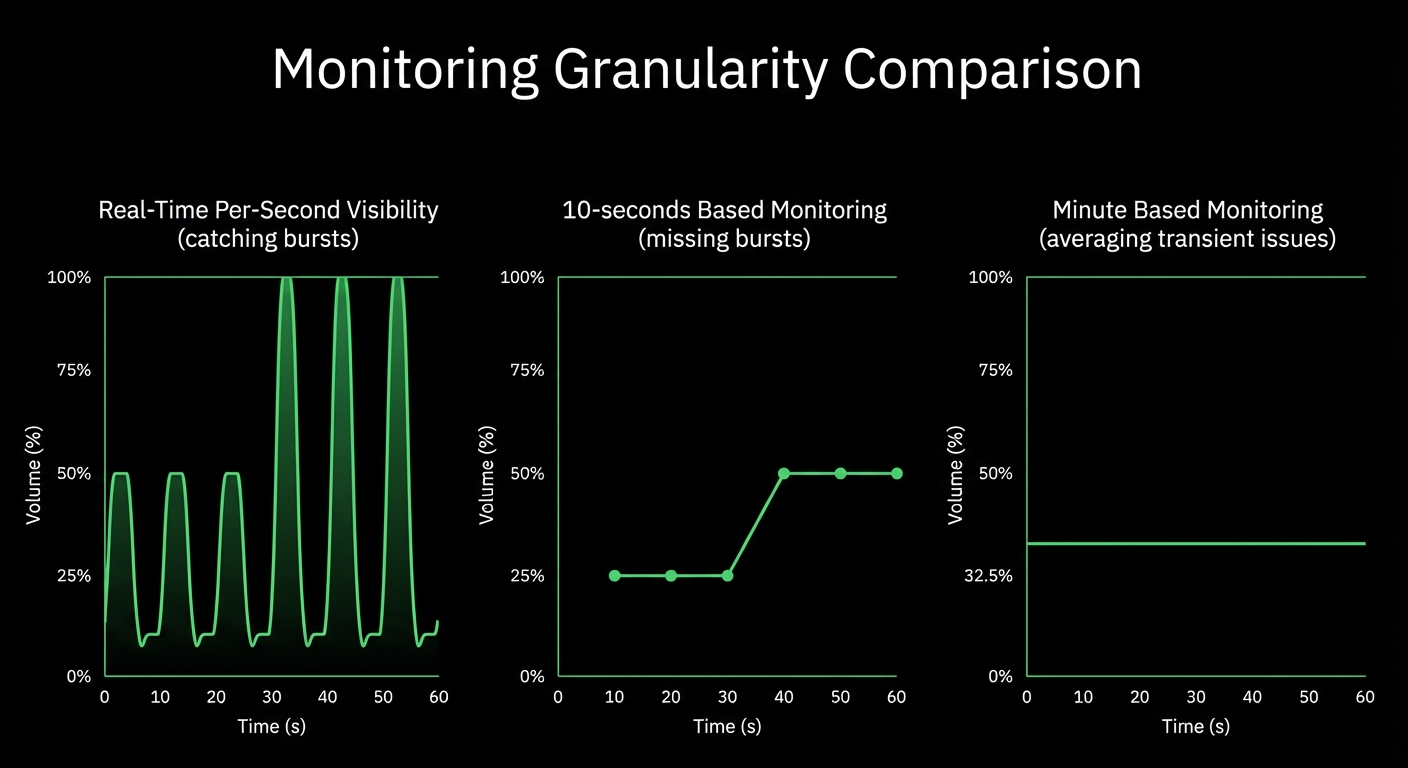
Per-second data collection with sub-2-second latency. See problems as they happen, not minutes later when it’s too late.
ML on Every Metric
18 unsupervised models per metric detect anomalies automatically with 99% false positive reduction. No manual tuning required.
60-Second Deployment
From installation to first dashboard in 60 seconds. Auto-discovery, algorithmic dashboards, and 400+ pre-configured alerts work instantly.
90% Cost Reduction
Transparent per-node pricing for infrastructure monitoring, with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers, at a fraction of competitor costs.
Complete Data Sovereignty
Metrics, logs and traces stay on your infrastructure. Only metadata routes to Cloud for unified dashboards and team collaboration.
Root Cause in 30-50 Metrics
Anomaly Advisor correlates thousands of metrics and surfaces root cause in top 30-50 results. AI explains what broke and why.
Trusted by DevOps teams worldwide








Transform Infrastructure Operations
Catch Problems Before They Cascade
80% faster MTTR
Learn about real-time monitoring

Precision Anomaly Detection
99% FP reduction
Explore ML anomaly detection


Troubleshoot Without SSH
Console replacement
See Netdata Functions


Scale Without Architectural Changes
Linear scaling
Understand edge architecture
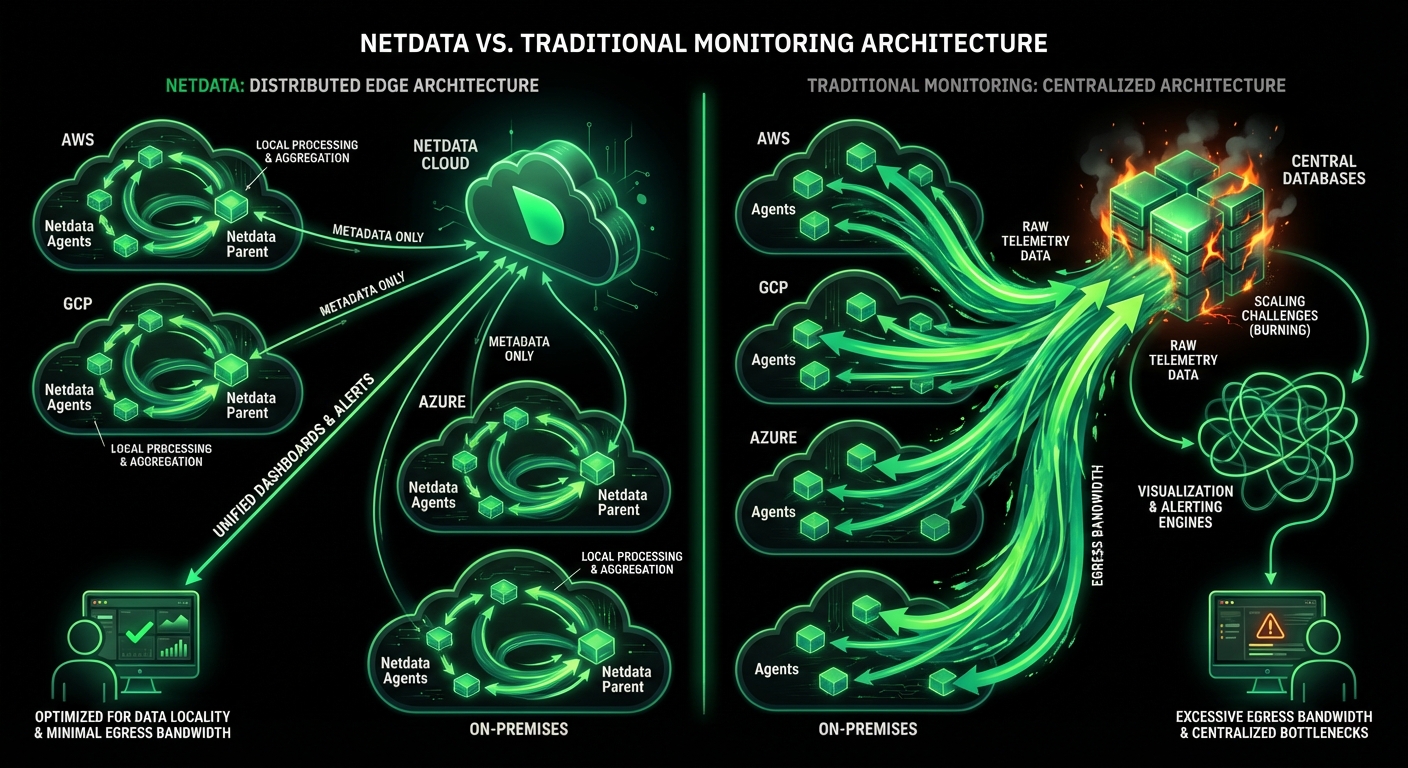

Keep Your Data Sovereign
100% on-premises
Learn about data sovereignty

Get Answers in Your Language
Zero query languages
Try AI troubleshooting


How Netdata Compares
Infrastructure Monitoring: Netdata vs Traditional Solutions
See how Netdata’s edge-native architecture delivers superior performance, lower costs, and simpler operations compared to centralized monitoring platforms.
Capability
Netdata
Traditional Monitoring
Data Collection
✅ Per-Second
True real-time, catches transient issues
⚠️ Per-Minute
Misses 90% of operational anomalies
Total Latency
✅ Sub-2 Seconds
Event to insight instantly
⚠️ 15-90 Seconds
Delayed visibility during incidents
Configuration
✅ Zero Required
Auto-discovery, instant dashboards
❌ Extensive Setup
Weeks to months deployment
ML Anomaly Detection
✅ All Metrics
18 models per metric, 99% FP reduction
⚠️ Selected Metrics
Manual configuration, high false positives
Data Sovereignty
✅ Complete
All data stays on-premises
❌ Centralized
Data egress to vendor cloud
Pricing Model
✅ Per-Node
Predictable per-node pricing, no charges for metrics volume
❌ Complex Volume-Based
Per-host + metrics + logs + containers
Cost Predictability
✅ Transparent
P90 billing excludes spikes
❌ Unpredictable
Volume-based billing leads to surprise costs
Sample Completeness
✅ 100%
Zero data loss, no sampling
⚠️ 85-95%
Sampling to reduce costs
Storage Efficiency
✅ 0.6 bytes/sample
Industry-leading compression
⚠️ 2-16 bytes/sample
Higher storage costs
Scalability
✅ Linear
No architectural changes 1-100k nodes
❌ Exponential
Complexity grows with scale
Query Languages
✅ None Required
Point-and-click NIDL framework
❌ PromQL/SQL Required
Steep learning curve
Troubleshooting
✅ AI-Powered
Natural language, root cause in 30-50 metrics
⚠️ Manual
Engineers hunt through dashboards
Complete Infrastructure Coverage
Monitor Every Server Detail
CPU per-core, memory breakdown, disk I/O, network bandwidth, filesystem usage, and hardware sensors - all at per-second granularity with ML anomaly detection.
Auto-discovered, zero configuration
Explore server monitoring


Why Infrastructure Teams Love Netdata
Real feedback from operations teams managing complex infrastructures
Instant Deployment Value
From installation to first dashboard in 60 seconds. Auto-discovery found everything we needed to monitor without any configuration.
True Real-Time Visibility
Per-second monitoring catches transient issues our previous minute-based tool completely missed. We finally see what’s happening.
Precision Anomaly Detection
18 models per metric means we see real anomalies, not statistical noise. The consensus-based approach is remarkably accurate.
Dramatic Cost Savings
Switched from our previous vendor and achieved 90% cost reduction. Predictable per-node pricing with no surprises from metrics volume.
Data Sovereignty Matters
All our metrics stay on-premises. Only metadata goes to Cloud for dashboards. Perfect for our compliance requirements.
Root Cause in Minutes
Anomaly Advisor surfaces the root cause in top 30-50 metrics. What used to take an hour now takes 3 minutes.
No Query Languages
Point-and-click analysis means our entire team can troubleshoot effectively. No PromQL experts required.
Scales Effortlessly
Went from 50 to 500 nodes with zero architectural changes. Cost and performance scaled linearly.

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.
August 17, 2026
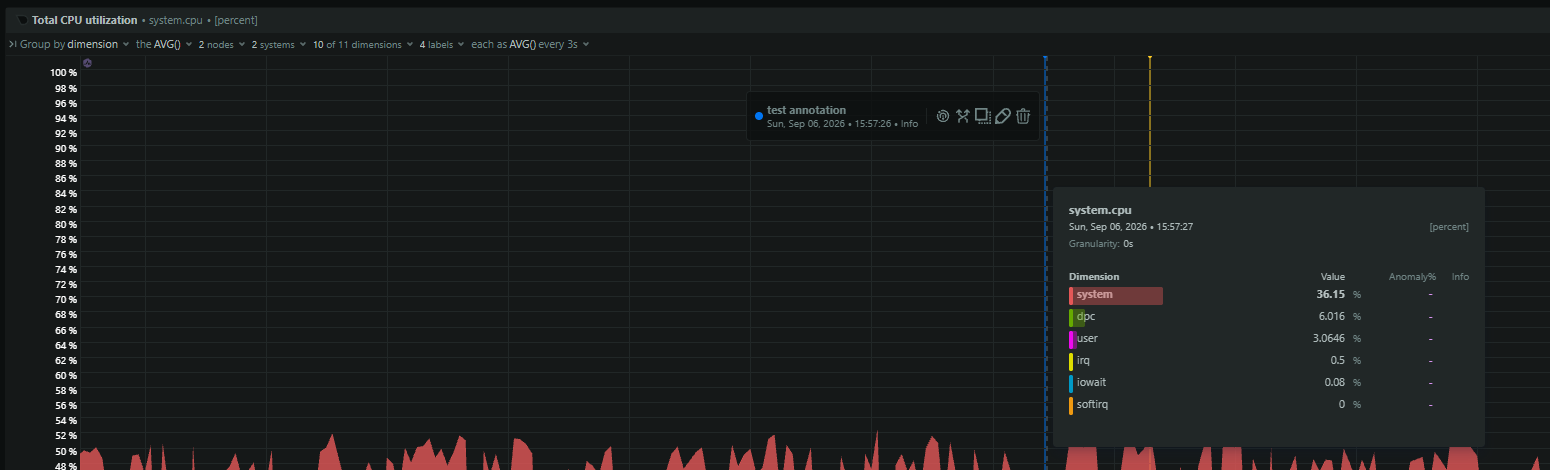
Chart Annotations For Deploys, Incidents & Changes
Netdata Cloud now lets you pin notes to a specific moment on a chart — deployments, incidents, config changes, maintenance windows — shared across your whole Space and one click away from a root-cause correlation.