



 Platform Architecture
Monitor Without Interruption
Maintain complete visibility during deployments, infrastructure changes, and network partitions. Netdata’s distributed edge-native architecture ensures monitoring remains operational when you need it most - delivering sub-2-second insights with automatic failover and zero data loss.

Resilient by Design
Built for operational continuity
No Single Point of Failure
Distributed architecture with autonomous agents ensures monitoring continues even when central systems are unavailable
Sub-2-Second Visibility
Per-second data collection with 1-second visualization latency reveals deployment issues immediately, not minutes later
Automatic Failover
Active-active parent clustering with instant failover and streaming replication eliminates monitoring downtime
ML Anomaly Detection
18-model ensemble consensus achieves 99% false positive reduction in anomaly detection through multi-model agreement
Production-Safe Overhead
Less than 5% CPU and 150-200 MB RAM per node - validated as most energy-efficient by university research
Predictable Economics
Flat per-node pricing with 90% cost reduction - no penalties for the visibility you need during deployments
Trusted by operations teams worldwide








Operational Continuity When It Matters Most
Survive Network Partitions
100% data completeness
Learn about distributed architecture

Deploy With Confidence
80% faster MTTR
Explore real-time monitoring


Update Without Downtime
Zero monitoring downtime
View scalability documentation


ML-Powered Signal Quality
99% false positive reduction
Discover ML capabilities


Architecture Comparison
Distributed vs Centralized Monitoring
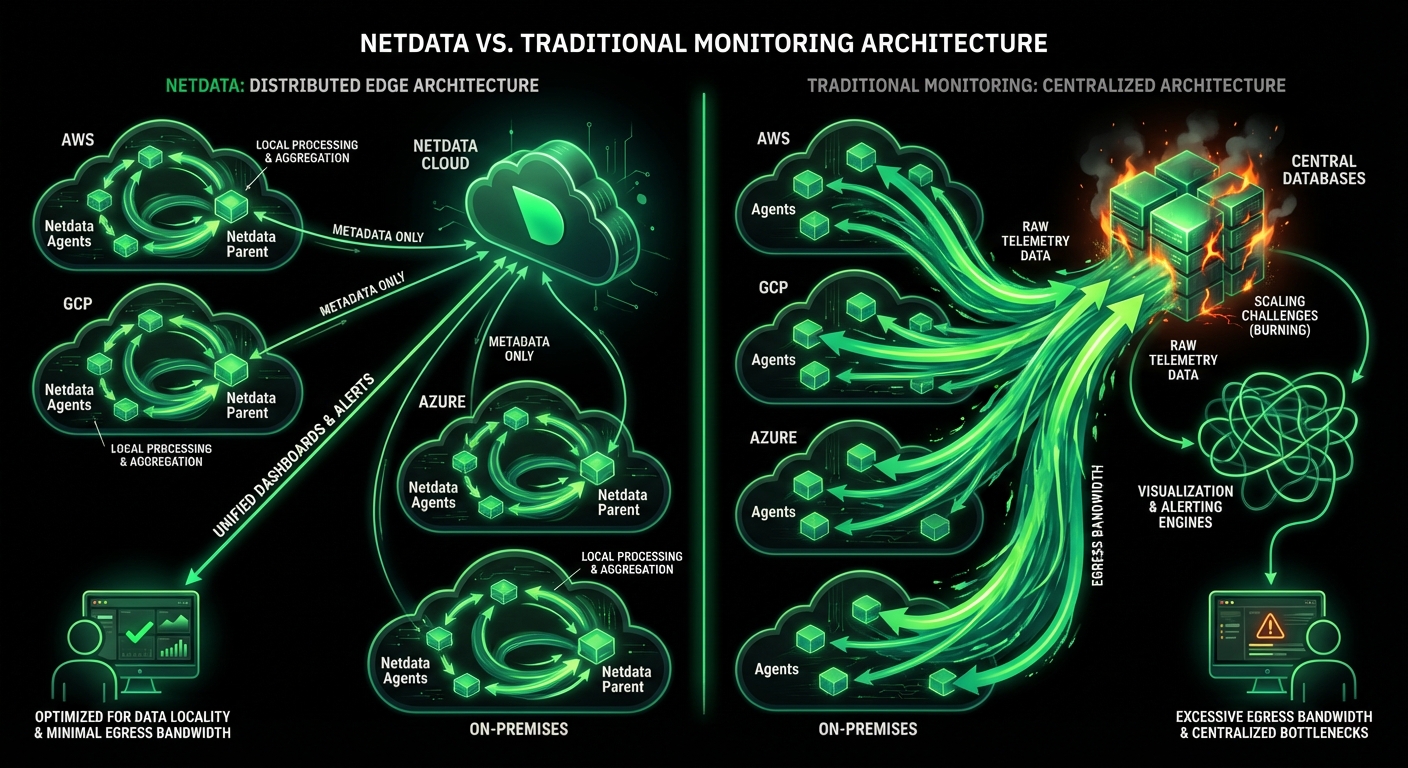
Traditional centralized monitoring creates single points of failure. Netdata’s distributed architecture ensures monitoring remains operational during the moments you need it most.
Capability
Netdata
Traditional Monitoring
Network Partition Resilience
✅ Continues Locally
Agents operate autonomously, buffer data, auto-replay
❌ Complete Blind Spot
Centralized systems lose all visibility
Data Collection Latency
✅ Sub-2-Second
1-second collection plus 1-second visualization
⚠️ 30-60 Seconds
Pipeline delays compound during deployments
Agent Resource Overhead
✅ Less than 5% CPU
150-200 MB RAM, university-validated efficiency
⚠️ 2-5% CPU
Higher overhead compounds system stress
High Availability
✅ Active-Active
Automatic failover, streaming replication
⚠️ Complex Setup
Requires manual federation configuration
Data Loss During Outages
✅ Zero Loss
Local buffering with automatic replay
❌ Gaps in Data
Missing data during connectivity issues
Update Coordination
✅ Rolling Updates
Zero downtime, automatic rollback
⚠️ Planned Downtime
Maintenance windows required
ML Anomaly Detection
✅ 99% False Positive Reduction
18-model consensus improves anomaly signal quality
⚠️ Basic Detection
Single-model approaches generate more noise
Deployment Visibility
✅ Real-Time
Per-second visibility across all instances
⚠️ Delayed
Pipeline latency obscures deployment impact
Cost Model
✅ Per-Node
Predictable pricing, no per-metric charges
⚠️ Volume-Based
Penalties for high-resolution data
Resilience Features
Complete Independence
Every Netdata agent is a full observability engine - collecting, storing, analyzing, alerting, and visualizing independently. When parents or cloud become unreachable, agents continue operating with local dashboards at http://localhost:19999.
Zero central dependency
Learn about edge architecture


Deployment Visibility That Prevents Cascading Failures
Traditional monitoring’s delayed visibility allows deployment issues to cascade before detection. Netdata’s sub-2-second latency catches problems immediately.
30-60 Second Monitoring Latency
Traditional pipeline delays
Issues Cascade Before Detection
Problems spread across infrastructure unnoticed
Netdata Sub-2-Second Visibility
Per-second collection plus 1-second visualization
Immediate Problem Detection
Catch regressions in the first seconds
Sampling-Based Data Collection
10-30 second intervals miss transient issues
Blind Spots During Rollouts
See only a fraction of actual behavior
Netdata 100% Sample Completeness
Every metric, every second, no sampling
Complete Deployment Visibility
Full fidelity analysis of rollout impact
Centralized Architecture
Single point of failure for visibility
Monitoring Blind Spots
Network issues cause complete data loss
Netdata Distributed Architecture
Autonomous agents with local buffering
Continuous Visibility
Monitoring continues during any outage
Key Capabilities
Comprehensive resilience features for operational continuity
Distributed Edge Architecture
Every agent operates autonomously with complete observability capabilities - no central dependencies or single points of failure
Automatic Failover Protection
Active-active parent clustering with instant failover and streaming replication ensures monitoring never stops
Local Operation During Outages
Agents continue collecting, storing, and alerting locally during network partitions - then automatically replay buffered data
Sub-2-Second Real-Time Visibility
Per-second data collection with 1-second visualization latency reveals deployment issues immediately
ML-Powered Anomaly Detection
18-model ensemble consensus achieves 99% false positive reduction - improving anomaly signal quality
Zero-Downtime Updates
Rolling agent updates with automatic rollback and strong backwards compatibility - no coordination required
Comprehensive Auto-Discovery
Zero-configuration detection of infrastructure and services with automatic dashboard generation
100% Data Completeness
Local buffering with automatic replay ensures zero data loss during connectivity issues
Production-Safe Overhead
Less than 5% CPU and 150-200 MB RAM per node - validated as most energy-efficient by university research

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.

October 3, 2026
Who Built This Dashboard, and Are They Still Here?
Your server monitoring dashboard shouldn't be a DIY project. Netdata charts every metric automatically — no query languages, no dashboards to build, ever.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.