



 Infrastructure Monitoring for AI Workloads
Keep Your LLM Infrastructure Running at Peak Performance
Monitor the infrastructure powering your LLM applications with per-second visibility into GPUs, containers, databases, and system resources. Detect bottlenecks before they impact inference latency, optimize resource utilization, and reduce cloud costs - all with zero configuration.

Infrastructure Visibility That Scales With Your AI Workloads
Comprehensive monitoring for the systems running your LLM applications
Real-Time GPU Monitoring
Track NVIDIA and AMD GPU utilization, memory, temperature, and PCIe bandwidth per-second to optimize inference performance and prevent thermal throttling.
Container Resource Tracking
Monitor CPU, memory, network, and disk usage for every Kubernetes pod and container running LLM inference servers, vector databases, and supporting services.
Database Performance Insights
Track PostgreSQL, MongoDB, and vector database query performance, connection pools, and storage I/O to prevent retrieval bottlenecks in RAG applications.
Instant Anomaly Detection
ML-powered anomaly detection on every metric identifies resource saturation, memory leaks, and performance degradation before they cause LLM failures.
Cost Optimization Intelligence
Identify overprovisioned GPU nodes and right-size container resources with per-second utilization data - reduce cloud costs by 30-50% without impacting performance.
Zero-Configuration Deployment
Auto-discovers Kubernetes clusters, GPU nodes, databases, and caches in 60 seconds. No manual configuration, no query languages, no dashboard building required.
Trusted by organizations running AI workloads at scale







Infrastructure Monitoring That Keeps AI Applications Running
Detect Infrastructure Bottlenecks Before They Impact Inference
80% faster MTTR
Learn about real-time monitoring

Optimize Cloud Costs Without Sacrificing Performance
90% cost reduction vs commercial APMs
See pricing

Troubleshoot Complex AI Infrastructure With Confidence
Sub-2-second latency from event to insight
Explore AI troubleshooting

Deploy Monitoring in Minutes, Not Weeks
60 seconds to first dashboard
Get started

Infrastructure Monitoring Comparison
Netdata vs Traditional Monitoring for AI Workloads
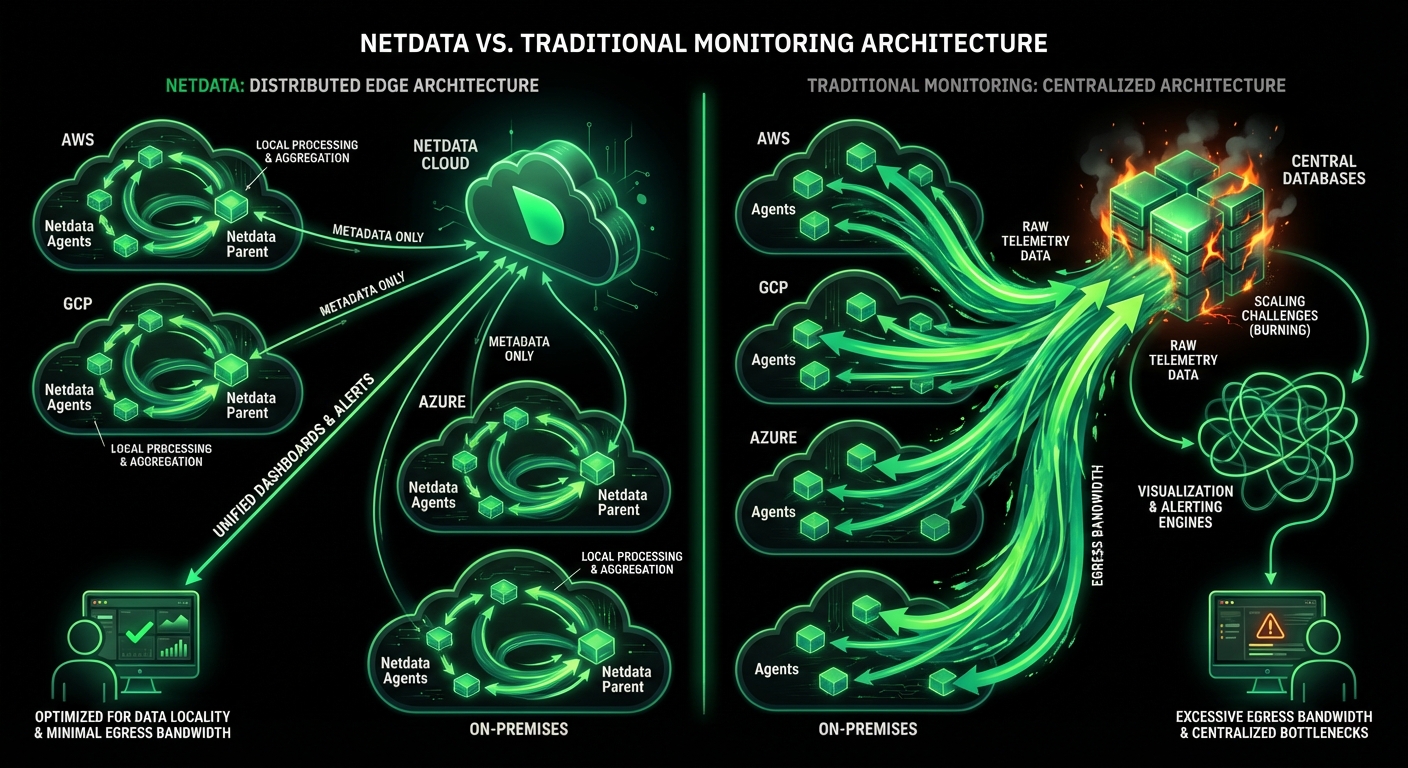
See how Netdata’s edge-native architecture delivers superior infrastructure visibility at a fraction of the cost
Capability
Netdata
Traditional Monitoring
Data Granularity
✅ Per-Second
Catch transient GPU spikes and bottlenecks
⚠️ Per-Minute or Worse
Miss critical infrastructure events
GPU Monitoring
✅ Advanced
NVIDIA/AMD utilization, memory, temperature, PCIe bandwidth
⚠️ Basic
Limited GPU metrics, manual configuration
Container Visibility
✅ Comprehensive
Per-pod CPU, memory, network, disk with auto-discovery
⚠️ Limited
Requires manual instrumentation and labels
Anomaly Detection
✅ Automated
ML on every metric, 99% false positive reduction
⚠️ Manual
Static thresholds, high false positive rate
Setup Time
✅ 60 Seconds
One-line install, auto-discovery, instant dashboards
❌ Days to Weeks
Complex configuration, manual dashboard building
Query Language
✅ None Required
Point-and-click analysis, no PromQL needed
❌ Required
PromQL, SQL, or custom query languages
Pricing Model
✅ Predictable
Per-node pricing, no per-metric charges
❌ Unpredictable
Per-metric/log charges, surprise bills
Data Sovereignty
✅ On-Premises
All data stays local, SOC 2 Type 2 certified
⚠️ Cloud-Only
Data egress required, compliance challenges
Complete Infrastructure Visibility for AI Workloads
Track GPU Performance in Real-Time
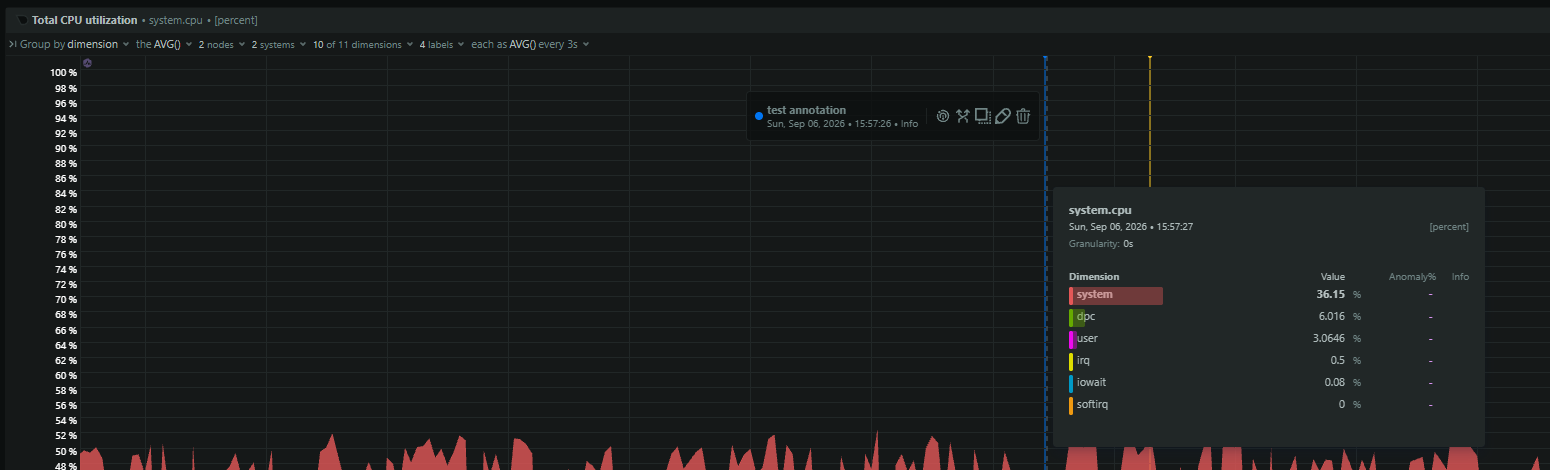
Monitor NVIDIA and AMD GPU utilization, memory usage, temperature, fan speed, power consumption, and PCIe bandwidth per-second. Detect thermal throttling, memory saturation, and performance degradation before they impact inference latency.
Per-second GPU metrics with ML anomaly detection
Learn more about GPU monitoring

Infrastructure Monitoring Essentials for AI Workloads
Key capabilities that keep your LLM infrastructure running smoothly
Real-Time Performance Tracking
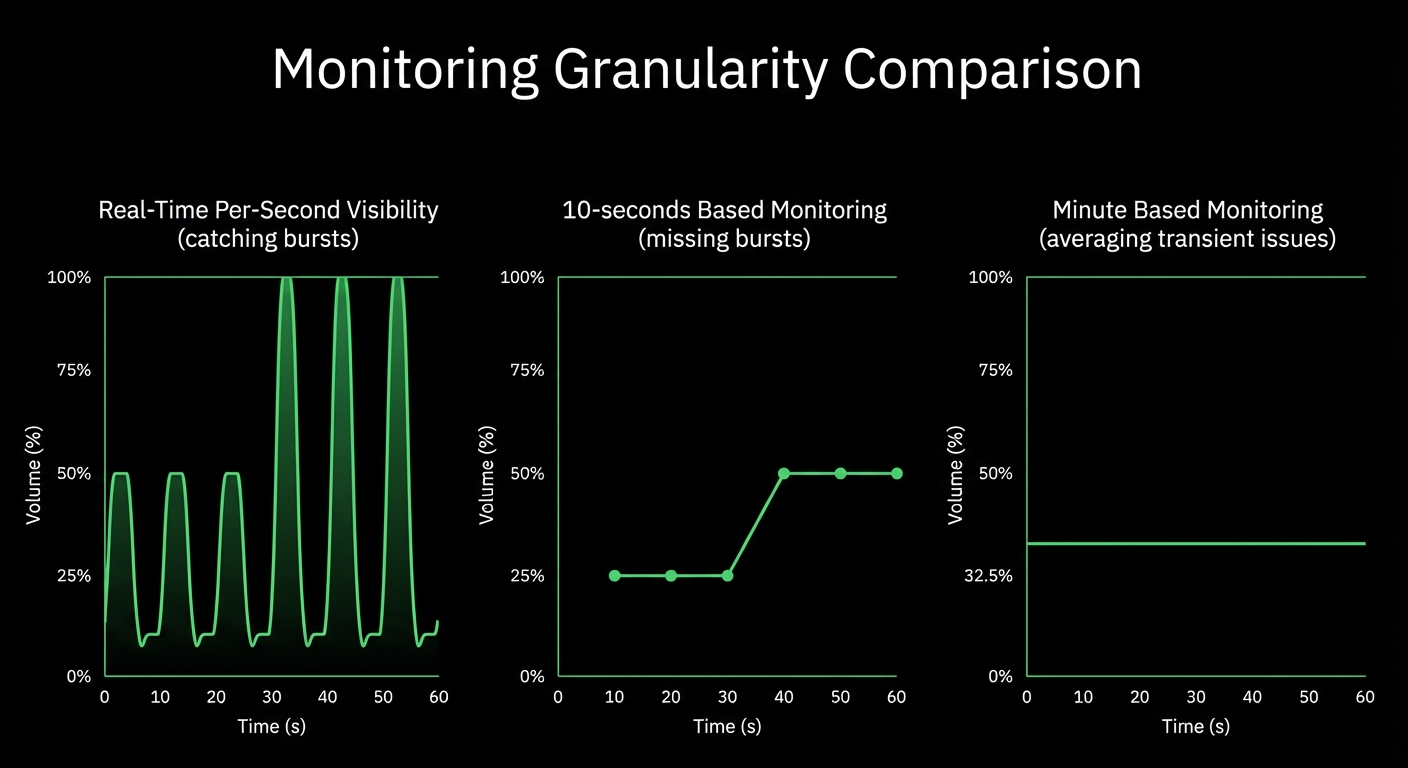
Per-second metrics reveal transient issues and microbursts that minute-level monitoring misses, enabling faster troubleshooting and optimization.
ML-Powered Anomaly Detection
Unsupervised machine learning on every metric identifies resource saturation and performance degradation automatically with 99% false positive reduction.
Automatic Infrastructure Discovery
Zero-configuration deployment auto-discovers Kubernetes clusters, GPU nodes, databases, and supporting services in 60 seconds.
Intelligent Root Cause Analysis
Anomaly Advisor correlates infrastructure issues across components, surfacing root causes in the top 30-50 metrics automatically.
Predictable Cost Structure
Predictable per-node pricing for infrastructure monitoring, with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers, makes budgets easy to forecast.
Data Sovereignty by Design
All observability data stays on-premises by default, supporting GDPR, HIPAA, and data residency requirements.

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.

October 3, 2026
Who Built This Dashboard, and Are They Still Here?
Your server monitoring dashboard shouldn't be a DIY project. Netdata charts every metric automatically — no query languages, no dashboards to build, ever.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.