





 Netdata vs Datadog
See Every Second of Your Infrastructure - Without the Enterprise Price Tag
Organizations monitoring infrastructure with Datadog often discover they’re paying APM prices for capabilities Netdata delivers at a fraction of the cost. Get true per-second visibility, zero-configuration deployment, OpenTelemetry traces stored on your own infrastructure, and 90% cost reduction on infrastructure monitoring.

Why Teams Choose Netdata Over Datadog
Built for infrastructure monitoring excellence
90% Cost Reduction
Fixed per-node pricing for infrastructure monitoring eliminates surprise bills. No charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers, so the bill does not punish scale.
True Real-Time Visibility
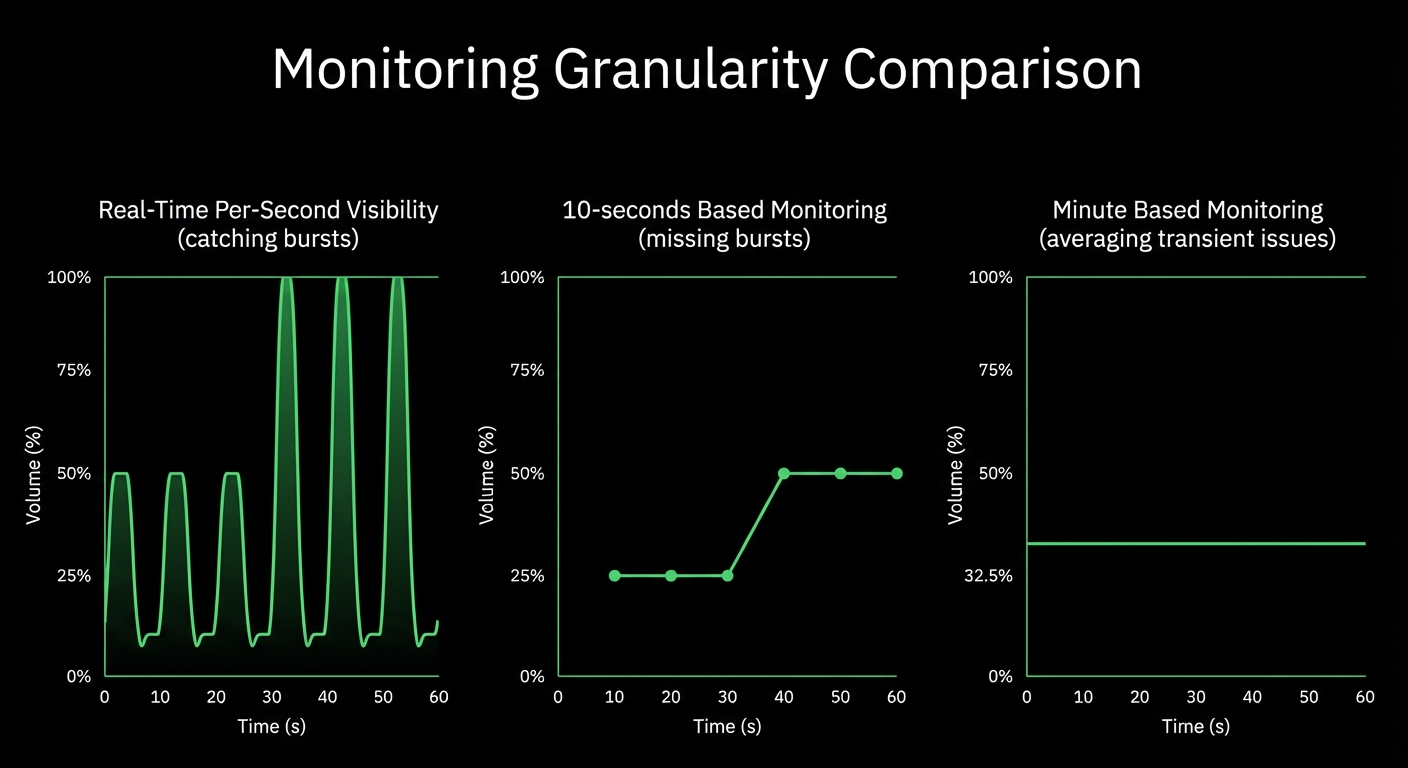
Per-second data collection with sub-2-second latency captures transient issues that minute-averaging completely misses.
Zero Configuration Required
60-second installation to first dashboard. Algorithmic dashboards and 400+ pre-configured alerts work instantly without manual setup.
ML on Every Metric
18 unsupervised models per metric provide 99% false positive reduction through consensus-based anomaly detection - automatically.
Edge-Native Architecture
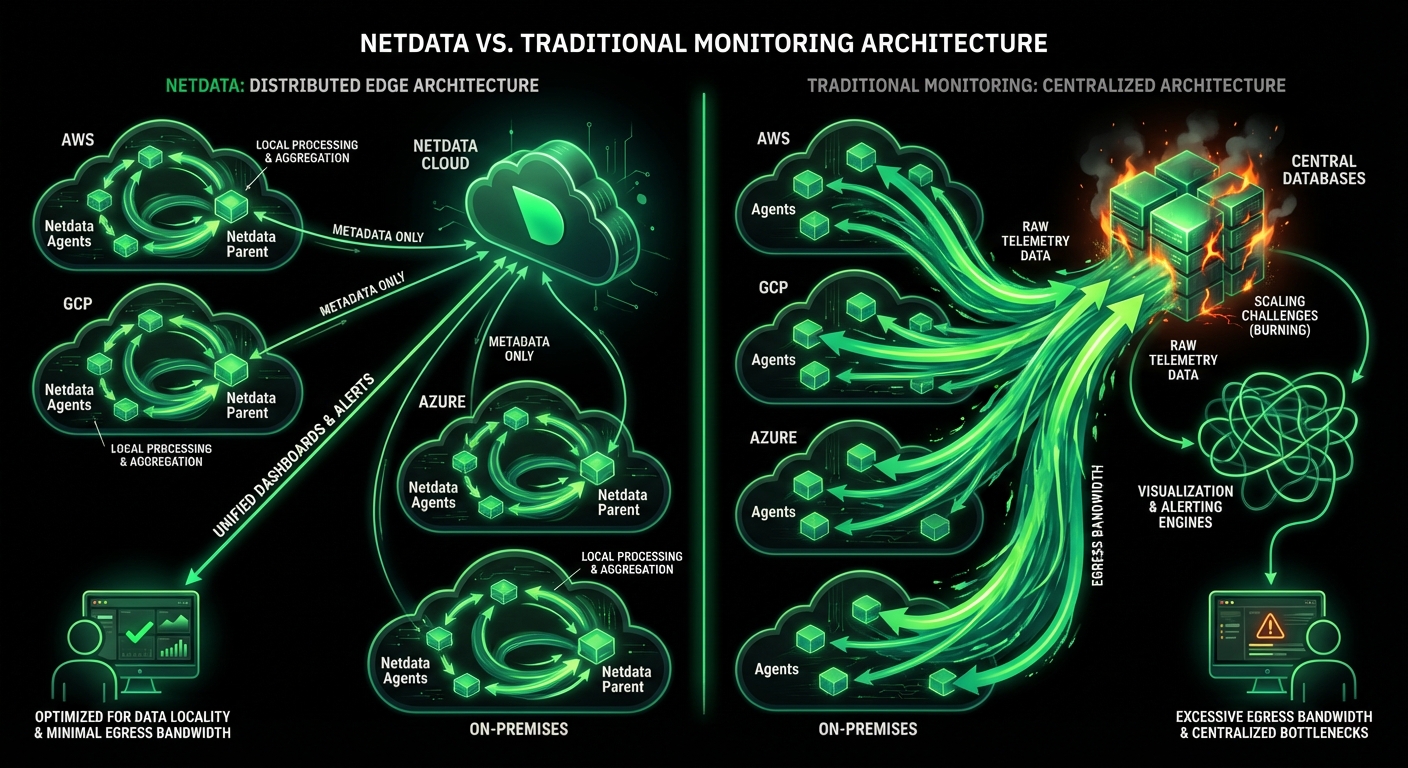
Process data where it lives, not where it’s expensive. Linear scalability with no central bottleneck as infrastructure grows.
Data Sovereignty by Design
Metrics, logs and traces stay on your infrastructure. Data residency, role-based access control and encrypted transport support GDPR, HIPAA, and other compliance requirements.
Trusted by DevOps teams worldwide







Datadog alternatives compared
If you’re looking for a Datadog alternative
Teams typically reach this page after a Datadog renewal estimate arrives. Here’s the broader alternatives landscape — pricing-model shape only, no list prices.
Alternative
Pricing model
Best fit
Netdata
Per-node, volume-discounted, no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers
Teams escaping per-host SaaS bill compounding; real-time troubleshooting; on-prem
Prometheus + Grafana
Open-source self-operated stack; cost is engineering time
Kubernetes-native shops with a platform team to operate the stack
New Relic
Usage-based ingest + per-user seats; permanent free tier
Mid-market teams with elastic workloads who want managed SaaS
SigNoz
Open-source APM (MIT); optional managed Cloud
OpenTelemetry-native teams wanting Datadog-shaped UX without SaaS bill
OpenObserve
Open-source AGPL; object-storage-backed for cheap retention
Logs-heavy workloads where Datadog’s index pricing hurts the most
Grafana Cloud
Active-series + ingest + per-user seats; LGTM managed
Teams who want LGTM’s architecture without operating Mimir / Loki / Tempo
Dynatrace
Per-host scaled by memory allocation
Enterprise APM-first on Java/.NET legacy where Davis AI pays off
Why teams leave Datadog
Conversations with teams switching off Datadog converge on the same three reasons. None of them are about capability.
First, the bill model. Per-host plus separate meters for custom metrics, log ingest, log indexing, APM, RUM, and synthetics. Each meter grows independently with workload, and the renewal estimate that arrives doesn’t look like the contract’s base rate. Teams who love Datadog have budget headroom; teams who leave have run out of it.
Second, cardinality pressure. Custom-metric pricing forces teams to drop labels they actually need — the user_id, the pod_uid, the request_id that would have explained which customer/instance/request was affected. The label discipline becomes a quarterly ritual. Then a customer escalation requires the label you dropped.
Third, the SaaS-only constraint. Datadog has no self-host option. For data-sovereignty workloads — regulated industries, EU operations, on-prem deployments — Datadog is structurally not the answer. Teams in this category leave for Netdata, Grafana, or Prometheus depending on operating-model preference.
The next sections compare Netdata against Datadog directly on each of these axes.
Platform Comparison
Netdata vs Datadog
How the platforms compare for infrastructure monitoring and observability
Capability
Netdata
Datadog
Data Collection Frequency
✅ 1 second
True real-time monitoring
⚠️ 10-15 seconds
Near real-time with delays
Visualization Latency
✅ Sub-2 seconds
Event to insight instantly
⚠️ 15-60 seconds
Pipeline processing delays
Architecture
✅ Distributed edge-native
No central bottleneck
⚠️ Centralized SaaS
Single point of processing
Setup Complexity
✅ 60 seconds
One-line install, instant dashboards
⚠️ Hours to days
Extensive configuration required
Learning Curve
✅ Hours to days
No query languages needed
⚠️ 4-8 weeks
Complex setup and training
Machine Learning
✅ All metrics automatic
18 models per metric, zero config
⚠️ Selective configured
Watchdog requires setup
Agent Resource Usage
✅ <5% CPU, 150-200MB RAM
Minimal production impact
⚠️ Higher overhead
Measurable performance impact
Data Sovereignty
✅ On-premises by default
Metrics, logs and traces stay local
⚠️ Centralized SaaS only
Data sent to vendor cloud
Sample Completeness
✅ 100% fidelity
Zero data loss, no sampling
⚠️ Sampling applied
Data loss from sampling
Pricing Model
✅ Fixed per-node
Predictable per node pricing
⚠️ Complex volume-based
Multiple usage charges
Cost Predictability
✅ Transparent billing
P90 protection, no surprises
⚠️ Unpredictable bills
Users report surprise charges
Distributed Tracing
✅ OpenTelemetry traces over OTLP, stored and indexed on your own agents, explored in the Traces tab (heatmap, waterfall, span details)
✅ Advanced
APM tracing with service maps and code profiling
Network Monitoring
Network Monitoring: Netdata vs Datadog, Head to Head
How the two compare on the network capabilities Netdata now ships natively.
Capability
Netdata
Datadog
SNMP Device Monitoring
✅ 100+ Vendor Profiles
v1/v2c/v3 (USM), zero-config auto-discovery, per-second where devices sustain it
✅ NDM
Network Device Monitoring (SNMP) module
Network Topology
✅ Live Maps
LLDP/CDP/BGP/OSPF device fabric plus per-process and container connection maps
⚠️ NPM Map
Service/cloud-oriented network map
Flow Analysis (NetFlow/sFlow/IPFIX)
✅ Built-In
NetFlow v5/v7/v9, IPFIX, sFlow v5: top talkers, Sankey, geo maps, no packet capture
✅ NPM
Network flow monitoring (usage-priced)
SNMP Traps
✅ Native Receiver
v1/v2c/v3 + INFORMs; 150,000+ trap definitions decoded and severity-tagged
⚠️ Limited
Traps via integrations, not a core feature
Collection Granularity
✅ Per-Second
1-second collection and visualization
⚠️ Not Per-Second
Polling/agent intervals, typically 15s+
ML Anomaly Detection
✅ Built-In
18 models per metric, ~99% fewer false positives
✅ Watchdog
ML anomaly detection on higher tiers
Full-Stack Scope
✅ Unified
Network + servers + apps + containers + logs + traces in one platform
✅ Broad
Full observability suite, priced by host + usage
Cost at Fleet Scale
✅ Per-Node
Flat per-node pricing; agents are open source; data can stay on-prem
⚠️ Host + Usage
NDM/NPM priced per device/host plus data usage; climbs with fleet size
Transform Your Infrastructure Monitoring
Eliminate Budget Anxiety
90% Cost Reduction
Calculate Your Savings
Catch Issues Before They Cascade
10-60× Faster Detection
See Real-Time Difference
Deploy in Minutes, Not Months
60-Second Time to Value
Start Monitoring Now


Scale Without Architectural Rewrites
Linear Scalability
Explore Architecture


Feature Comparison
Monitoring Features Side by Side
Comprehensive feature comparison for infrastructure monitoring
Feature
Netdata
Datadog
Infrastructure Metrics
✅ Ideal coverage
All OS, hardware, network metrics
✅ Advanced coverage
Comprehensive infrastructure monitoring
Container Monitoring
✅ Included in host
Complete cgroups visibility
⚠️ Additional charges
Per-container pricing applies
Kubernetes Support
✅ DaemonSet native
Auto-discovery, pod metrics
✅ Advanced support
Orchestrator Explorer
Process Monitoring
✅ Advanced coverage
apps.plugin comprehensive
✅ Good coverage
Process visibility available
Hardware Sensors
✅ Ideal native support
IPMI, EDAC, RAPL, GPUs
⚠️ Limited coverage
Basic hardware monitoring
Log Management
✅ Advanced
OS logs in place + any source via OpenTelemetry
⚠️ Volume-based pricing
Ingestion and indexing charges
Custom Metrics
✅ No per-metric charges
No custom-metric meter
⚠️ Additional charges
Per-metric pricing applies
Pre-Configured Alerts
✅ 400+ templates
Component-level auto-attach
⚠️ Build from scratch
Manual configuration required
Anomaly Detection
✅ All metrics automatic
18 models, 99% FP reduction
⚠️ Selective configured
Watchdog requires setup
Dashboard Building
✅ Automated generation
Algorithmic dashboards
⚠️ Manual building
Requires configuration
SNMP Monitoring
✅ Native included
Auto-discovery, no charges
⚠️ Additional charges
Network Device Monitoring
Synthetic Checks
✅ HTTP/TCP/DNS included
Basic synthetics built-in
⚠️ Additional charges
API and Browser tests
Netdata's Competitive Advantages
Predictable Pricing That Scales With You
Datadog's complex volume-based pricing creates unpredictable bills. Netdata's fixed per-node pricing for infrastructure monitoring eliminates billing anxiety with P90 protection and no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers.
90% cost reduction vs Datadog
Calculate Your Savings


Use Case Comparison
Netdata vs Datadog Use Cases
Which platform fits your monitoring needs
Use Case
Netdata
Datadog
Infrastructure Monitoring
✅ Ideal
Purpose-built, per-second visibility
✅ Advanced
Comprehensive but expensive
Container & Kubernetes
✅ Ideal
Complete cgroups, included in host
✅ Advanced
Full support, per-container charges
Edge & IoT Monitoring
✅ Ideal
<100MB RAM, works offline
❌ Not Supported
Too resource-heavy for edge
MSP & Hosting Providers
✅ Ideal
Per-node economics viable at scale
⚠️ Expensive
Per-host pricing challenging
Compliance & Data Sovereignty
✅ Ideal
On-premises, air-gapped capable
⚠️ Limited
SaaS only, data egress required
Real-Time Troubleshooting
✅ Ideal
Per-second, sub-2s latency
✅ Good
10-15s collection, pipeline delays
Distributed Tracing
✅ Good
OTel traces on your infrastructure, next to per-second metrics
✅ Advanced
Full APM with code profiling
Application Performance
🔹 OpenTelemetry tracing
RED analysis, waterfall and span details, next to per-second infrastructure metrics and logs on the same agent
✅ Advanced
Complete APM suite
Real User Monitoring
⚠️ Partial
Browser RUM with Core Web Vitals, JavaScript errors and sessions; no session replay
✅ Advanced
Session replay, conversion tracking
Log Management
✅ Ideal
OS logs in place + any source via OpenTelemetry
✅ Good
Advanced but volume-based pricing
Cost Optimization
✅ Ideal
90% reduction, predictable pricing
⚠️ Expensive
Complex, unpredictable bills
Lean Team Operations
✅ Ideal
Zero-config, skill democratization
⚠️ Challenging
Requires specialists, 4-8 week ramp
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.

June 23, 2026
5 Best SolarWinds Alternatives for 2026
Discover the 5 best SolarWinds alternatives for 2026, built for the cloud-native, dynamic infrastructure legacy tools can't handle. Read the guide now!
June 23, 2026
SolarWinds Price Increases 2026: What Customers Need to Know
Facing SolarWinds price increases in 2026? Learn what changed, the real impact, and a practical way to evaluate your options. Read the full guide now!