



 Container Monitoring
See Every Container, Every Second, Without the Chaos
Traditional container monitoring drowns teams in complexity and costs. Netdata delivers per-second visibility across every container on every node with zero configuration, ML-powered insights, and predictable pricing - transforming how lean teams monitor dynamic infrastructure.

Why Container Monitoring Fails - And How Netdata Fixes It
The container monitoring revolution you’ve been waiting for
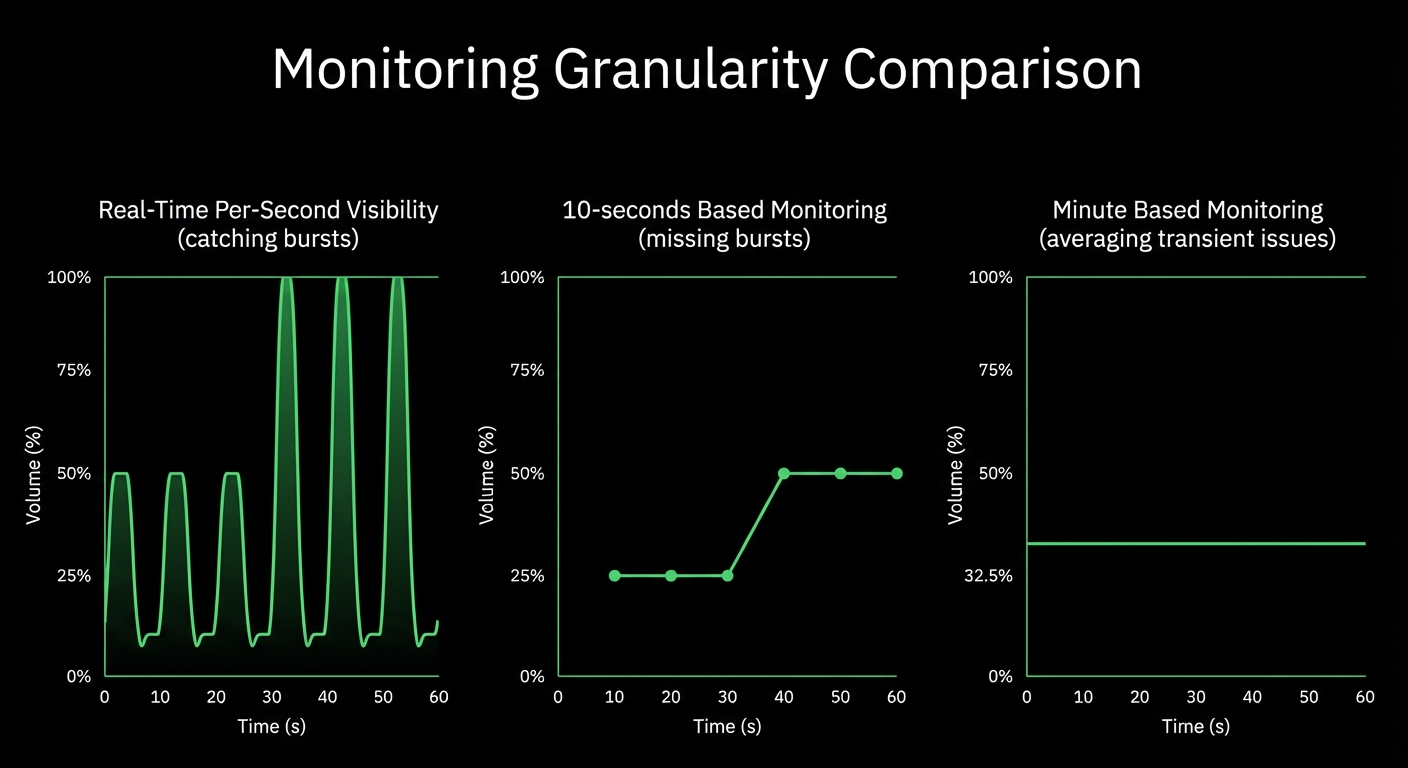
True Real-Time Visibility
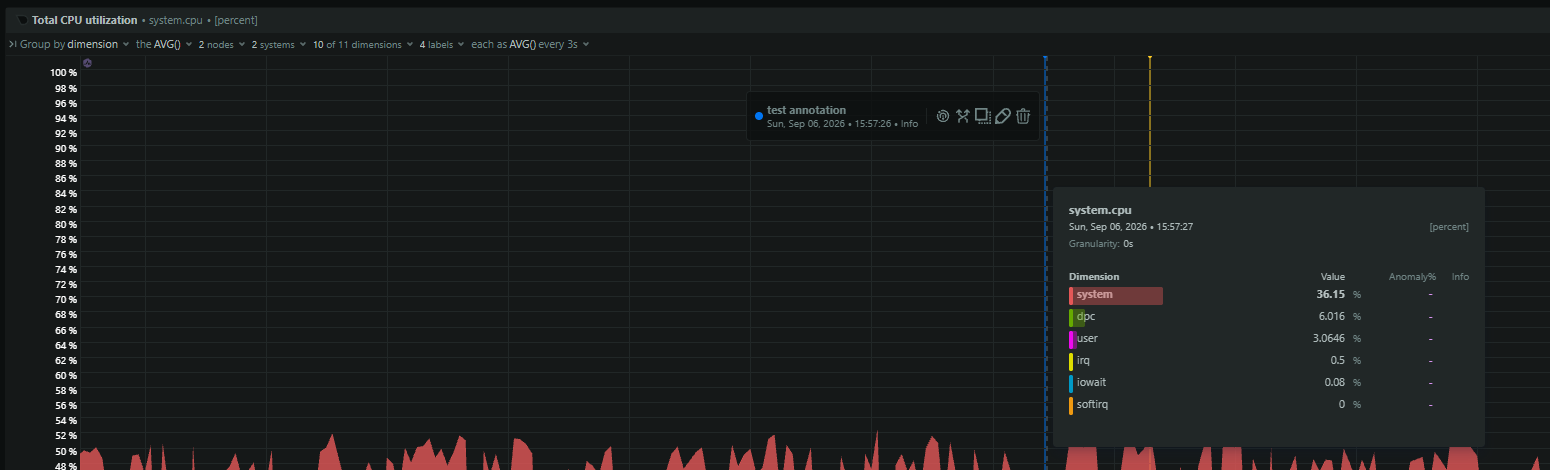
Per-second metrics capture microbursts and transients that minute-based tools miss. See exactly what’s happening now, not averaged approximations.
Predictable Container Costs
One agent monitors every container on the host, billed per node with no per-container charges. No surprise bills from autoscaling or container churn - 90% cost reduction vs traditional solutions.
ML Detects Issues Instantly
18 machine learning models per metric identify anomalies automatically. 99% false positive reduction in anomaly detection - you see real problems, not noise.
Zero Configuration Required
Auto-discovers containers, generates dashboards, configures alerts - all in 60 seconds. No PromQL, no YAML, no manual setup.
Root Cause in Seconds
Anomaly Advisor correlates thousands of metrics to surface root causes in top 30-50 results. AI explains what broke and why in plain English.
Complete Container Context
Monitor processes, network connections, logs, and metrics from the same source. Replace SSH debugging with browser-based troubleshooting plus history.
Trusted by teams monitoring millions of containers worldwide





Transform Container Operations
Catch Problems Before They Cascade
80% faster MTTR
Learn about real-time monitoring

Stop Paying for Every Container
90% cost reduction
See transparent pricing

Accurate Anomaly Detection
99% fewer false positives
Explore ML anomaly detection


Troubleshoot Without SSH
Console replacement
See Netdata Functions


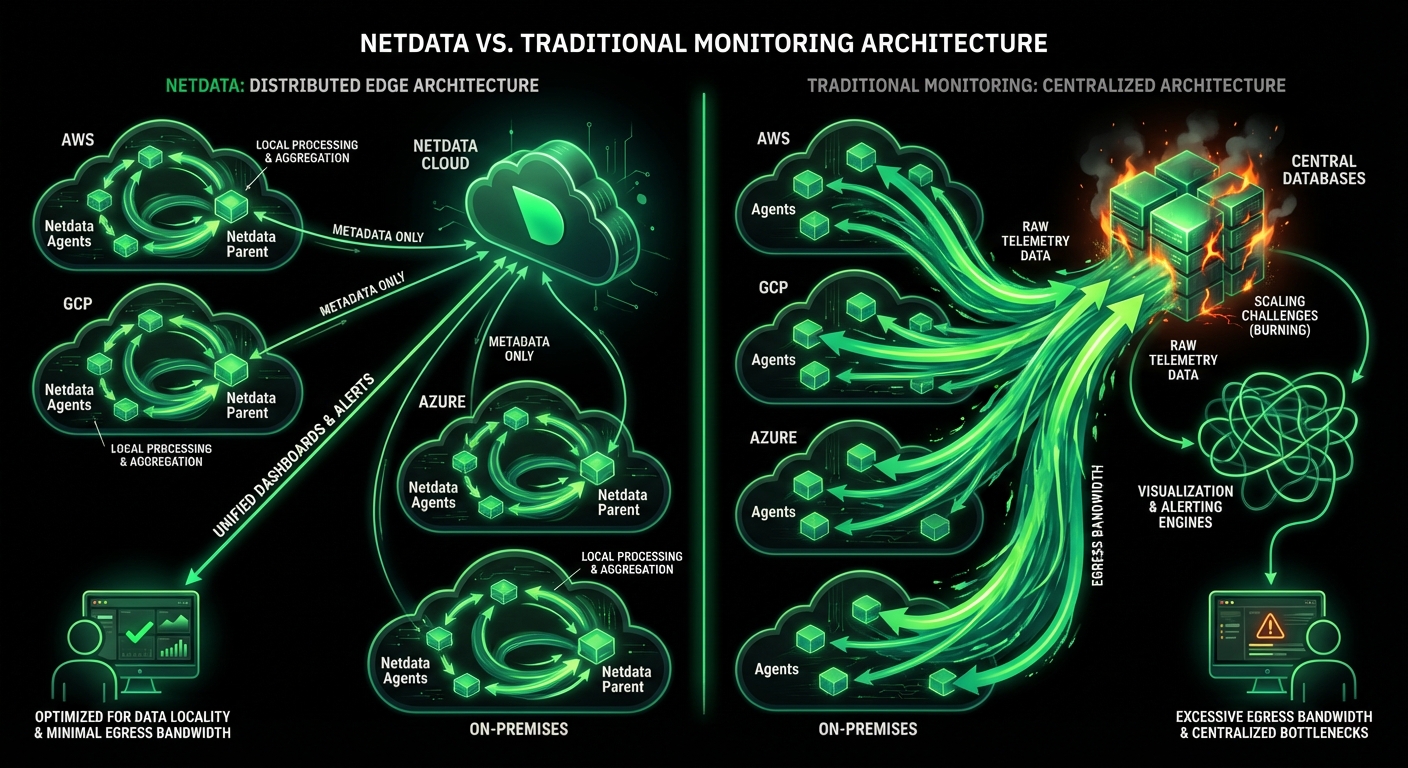
Scale Without Complexity
Linear scalability
Understand edge architecture

Get Answers in Your Language
Zero query languages
Try AI troubleshooting


Container Monitoring Reality Check
Netdata vs Traditional Container Monitoring
See how Netdata solves the pain points that plague traditional container monitoring solutions.
Capability
Netdata
Traditional Tools
Data Granularity
How often metrics are collected
✅ Per-Second
Captures microbursts and transients
⚠️ Per-Minute or Worse
Averages hide critical spikes
Container Pricing
How you’re charged for monitoring
✅ Per-Node Pricing
Billed per node, no per-container charges
❌ Per-Container Billing
Autoscaling creates surprise bills
Setup Complexity
Time from install to insights
✅ 60 Seconds
Auto-discovery, zero configuration
⚠️ Hours to Days
Manual dashboards and queries
Anomaly Detection
How issues are identified
✅ 18 ML Models Per Metric
99% fewer false positives
⚠️ Static Thresholds
Manual tuning required
Root Cause Analysis
Finding what actually broke
✅ Automated Correlation
Top 30-50 results in seconds
❌ Manual Investigation
Hours correlating metrics
Query Language
Skills required for analysis
✅ Point-and-Click
NIDL framework, no PromQL
⚠️ PromQL/SQL Required
Steep learning curve
Data Sovereignty
Where your metrics live
✅ On-Premises
All data stays in your infrastructure
⚠️ Centralized Cloud
Data egress and compliance issues
Scalability Model
How system handles growth
✅ Linear Scaling
1 to 100,000+ nodes same architecture
⚠️ Exponential Complexity
Requires architectural changes
MTTR Impact
Time to resolve incidents
✅ 80% Reduction
AI-powered troubleshooting
⚠️ Hours to Resolve
Manual correlation and analysis
Container Monitoring Capabilities
Complete Kubernetes Visibility
Monitor pods, nodes, deployments, and control plane with per-second granularity. Auto-discovers all Kubernetes resources and generates dashboards automatically.
Native K8s integration
Explore Kubernetes monitoring


Container Monitoring Best Practices
Essential capabilities for production container environments
Per-Second Granularity
Capture microbursts and transients that minute-based monitoring misses. See exactly what’s happening now, not averaged approximations.
ML Anomaly Detection
18 models per metric identify behavioral anomalies automatically. 99% false positive reduction in anomaly detection - you see real problems, not noise.
Instant Root Cause
Anomaly Advisor correlates thousands of metrics to surface root causes in top 30-50 results. AI explains what broke and why.
Complete Context
Monitor metrics, logs, processes, and network connections from the same source. No timestamp matching or separate systems.
Traces Next to Containers
Send OpenTelemetry traces from your containerized services to the same agent and follow every request across services in the Netdata Cloud Traces tab.
Zero Configuration
Auto-discovers containers, generates dashboards, configures alerts - all in 60 seconds. No PromQL, no YAML, no manual setup.
Predictable Costs
One agent monitors every container on the host, billed per node with no per-container charges. No surprise bills from autoscaling or container churn.
Linear Scalability
Monitor 1 to 100,000+ containers with the same architecture. Add nodes without affecting existing performance.
Data Sovereignty
Metrics, logs and traces stay on your infrastructure. Only metadata travels to Cloud for unified dashboards and team collaboration.
AI Troubleshooting
Ask questions in natural language via Model Context Protocol. AI generates automated reports in 2-3 minutes.

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.

October 3, 2026
Who Built This Dashboard, and Are They Still Here?
Your server monitoring dashboard shouldn't be a DIY project. Netdata charts every metric automatically — no query languages, no dashboards to build, ever.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.