



 Linux Monitoring & Observability
See Every Second of Your Linux Infrastructure
Netdata transforms Linux monitoring with per-second visibility, edge-based ML anomaly detection, and zero-configuration deployment. Monitor any number of servers with predictable per-node costs and instant insights - no query languages, no manual dashboards, no surprise bills.

Why DevOps Teams Choose Netdata for Linux
Complete visibility without the complexity
True Real-Time Monitoring
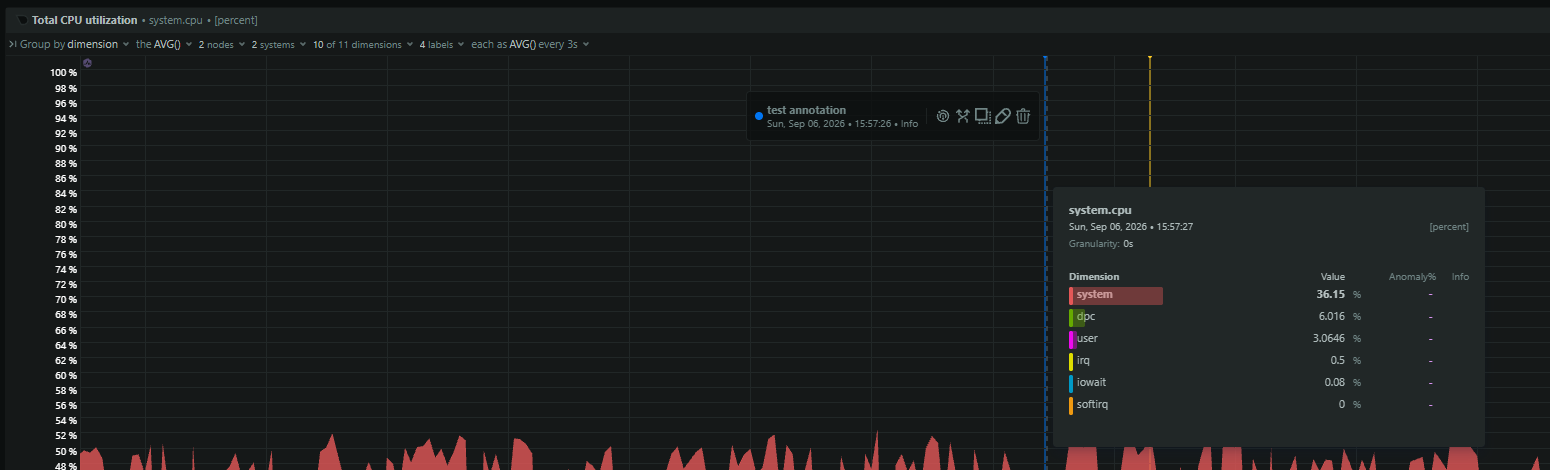
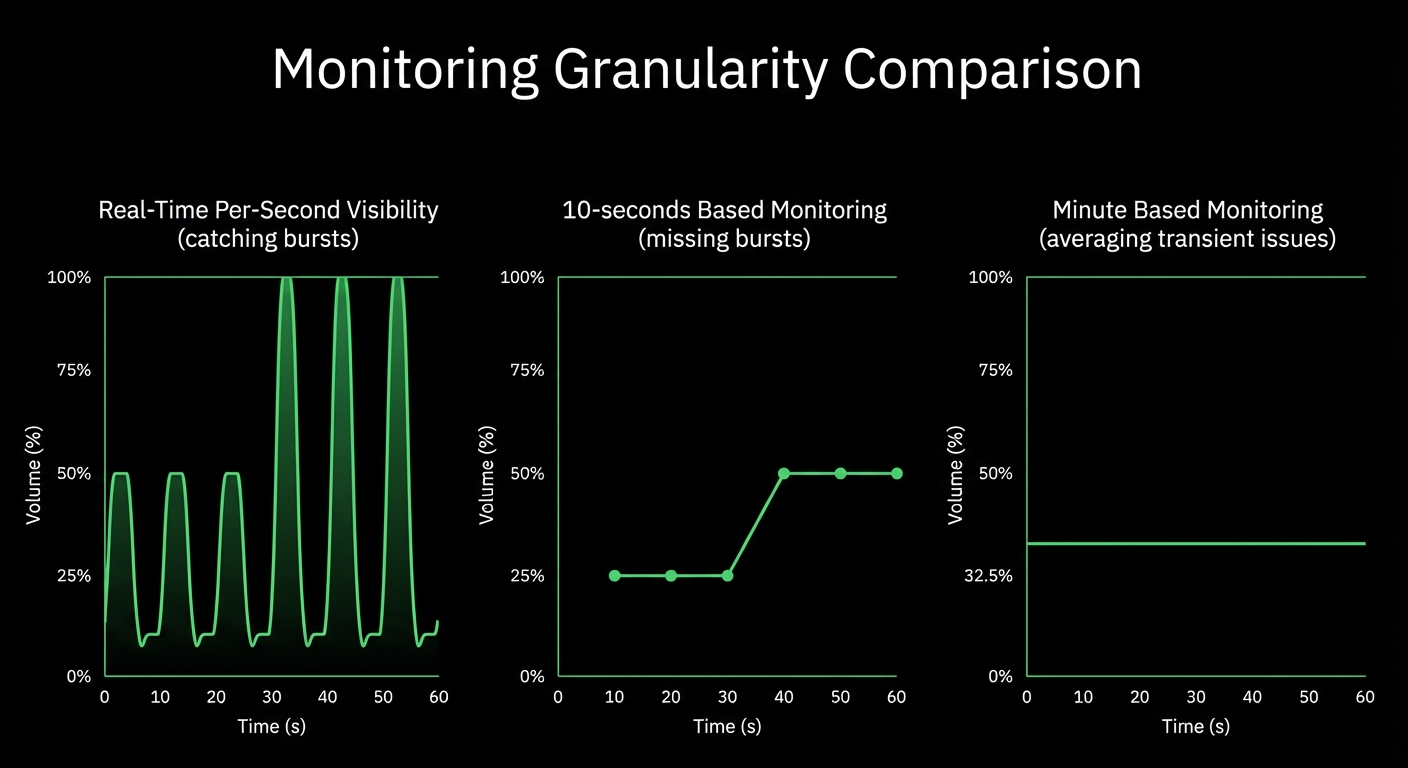
Per-second data collection with sub-2-second latency. Catch transient issues invisible to 10-60 second monitoring.
ML on Every Metric
18 unsupervised models per metric detect anomalies automatically. 99% false positive reduction through consensus.
60 Seconds to Production
One-line install, zero configuration. Auto-discovers services, generates dashboards, trains ML models instantly.
90% Cost Reduction
Predictable per-node pricing for infrastructure monitoring, with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers. No surprise bills.
Automatic Root Cause Analysis
Anomaly Advisor ranks thousands of metrics by relevance. Root cause in top 30-50 results within seconds.
Complete Platform Consolidation
Replace 7+ tools with one. Metrics, logs, traces, ML, AI, alerts, and console access unified in single agent.
Trusted by DevOps teams worldwide







Transform Linux Operations with Netdata
Actionable Alerts Through Intelligent Design
400+ pre-configured alerts
Learn about intelligent alerting

Slash Infrastructure Costs by 90%
Predictable per-node pricing
See pricing details
Accelerate Troubleshooting with AI-Powered Insights
80% MTTR reduction
Explore AI troubleshooting


Deploy Instantly with Zero Configuration
60 seconds to production
View installation guide


Scale Linearly from 1 to 100,000+ Nodes
100,000+ nodes proven
Learn about scalability

Manage Logs Without Pipelines or Indexing
90% log cost reduction
Discover zero-pipeline logs


Netdata vs Traditional Linux Monitoring
Why Netdata Outperforms Legacy Solutions
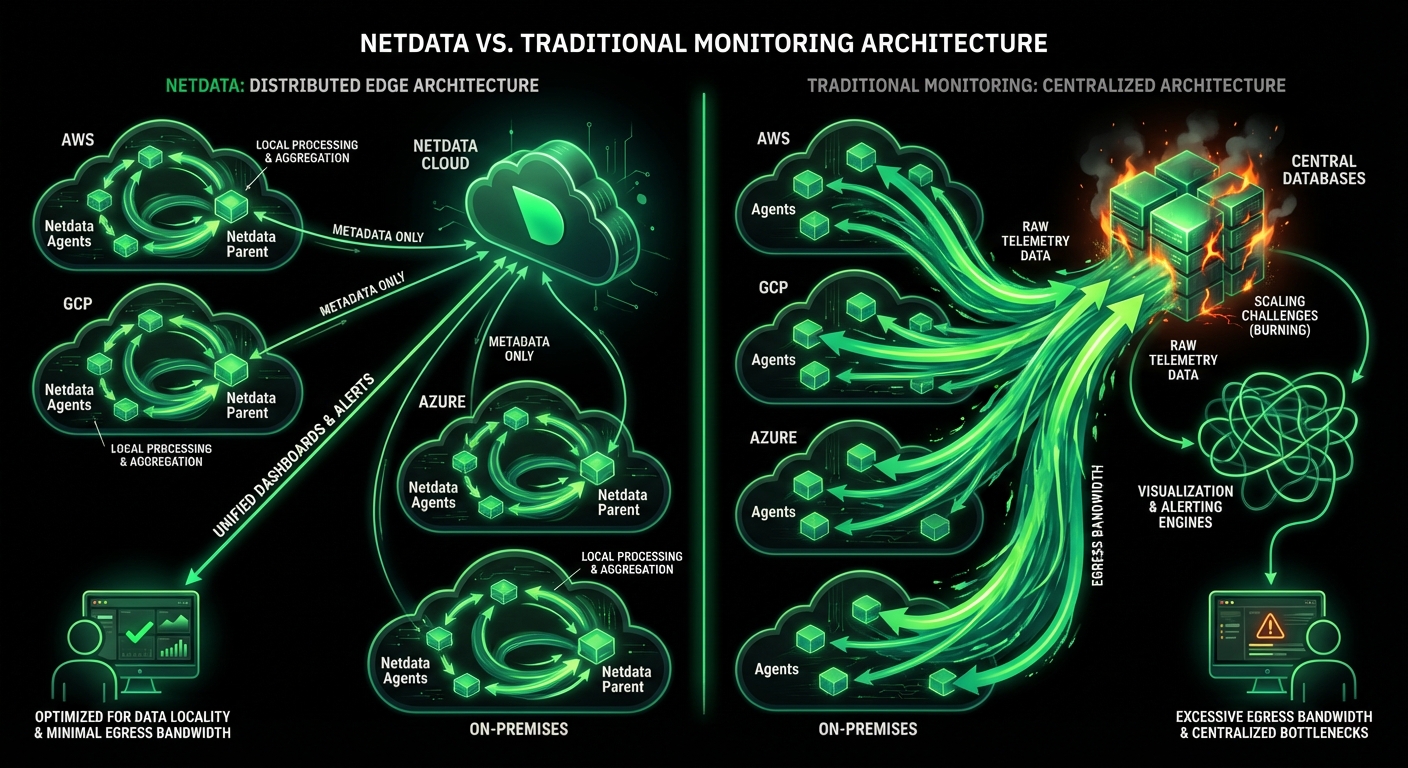
Traditional monitoring tools weren’t built for modern Linux infrastructure. See how Netdata’s edge-native architecture delivers superior capabilities at a fraction of the cost.
Capability
Netdata
Traditional Monitoring
Data Granularity
✅ Per-Second
Catch transient issues others miss
⚠️ 10-60 Seconds
Averages hide critical spikes
Setup Time
✅ 60 Seconds
One command, instant dashboards
❌ Days to Weeks
Manual config, dashboard building
Learning Curve
✅ Zero
Point-and-click, no query languages
❌ Weeks
PromQL, YAML, manual tuning
ML Anomaly Detection
✅ Every Metric
18 models per metric, automatic
⚠️ Selected Metrics
Manual configuration, paid add-on
Root Cause Analysis
✅ Automatic
Anomaly Advisor ranks all metrics
❌ Manual
Hours of hypothesis testing
Log Management
✅ Advanced
OS logs in place + any source via OpenTelemetry, 90% savings
❌ Complex Pipeline
Filebeat→Kafka→Logstash→ES
Pricing Model
✅ Predictable Per-Node
No charges for metrics volume or Logs Monitoring (querying logs in place)
❌ Volume-Based
Surprise bills, per-metric charges
Scalability
✅ Linear
100,000+ nodes proven
⚠️ Exponential Complexity
Federation, sharding required
Data Sovereignty
✅ Edge Storage
Data stays on-premises
❌ Centralized
Data moves to cloud/central DB
Tool Consolidation
✅ Complete Platform
Metrics, logs, traces, ML, AI, alerts
❌ 7+ Tools Required
Prometheus, Grafana, Loki, etc
Complete Linux Observability in One Platform
Per-Second Visibility Across All Systems
800+ auto-discovered integrations monitor CPU, memory, disk, network, processes, containers, and applications. ML-based anomaly detection on every metric with 99% false positive reduction.
10-60× faster than industry standard
Explore metrics management

Key Advantages for Linux Infrastructure
Why operations teams choose Netdata for Linux monitoring
True Real-Time Monitoring
Per-second data collection with sub-2-second latency. Catch transient issues invisible to 10-60 second monitoring.
ML on Every Metric
18 unsupervised models per metric detect anomalies automatically with 99% false positive reduction.
Zero Configuration
60 seconds from install to production. Auto-discovers services, generates dashboards, trains ML models.
Predictable Costs
Per-node pricing with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers. 90% savings vs traditional solutions.
AI-Powered Troubleshooting
Natural language queries, automatic root cause analysis, and AI-generated insights reduce MTTR by 80%.
Complete Platform
Replace 7+ tools with one. Metrics, logs, traces, ML, AI, alerts, and console access unified.
Linear Scalability
Proven at 100,000+ nodes. Distributed architecture scales without performance degradation.

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.

October 3, 2026
Who Built This Dashboard, and Are They Still Here?
Your server monitoring dashboard shouldn't be a DIY project. Netdata charts every metric automatically — no query languages, no dashboards to build, ever.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.