



 HPC Monitoring & Observability
See Every Microsecond That Matters in Your HPC Infrastructure
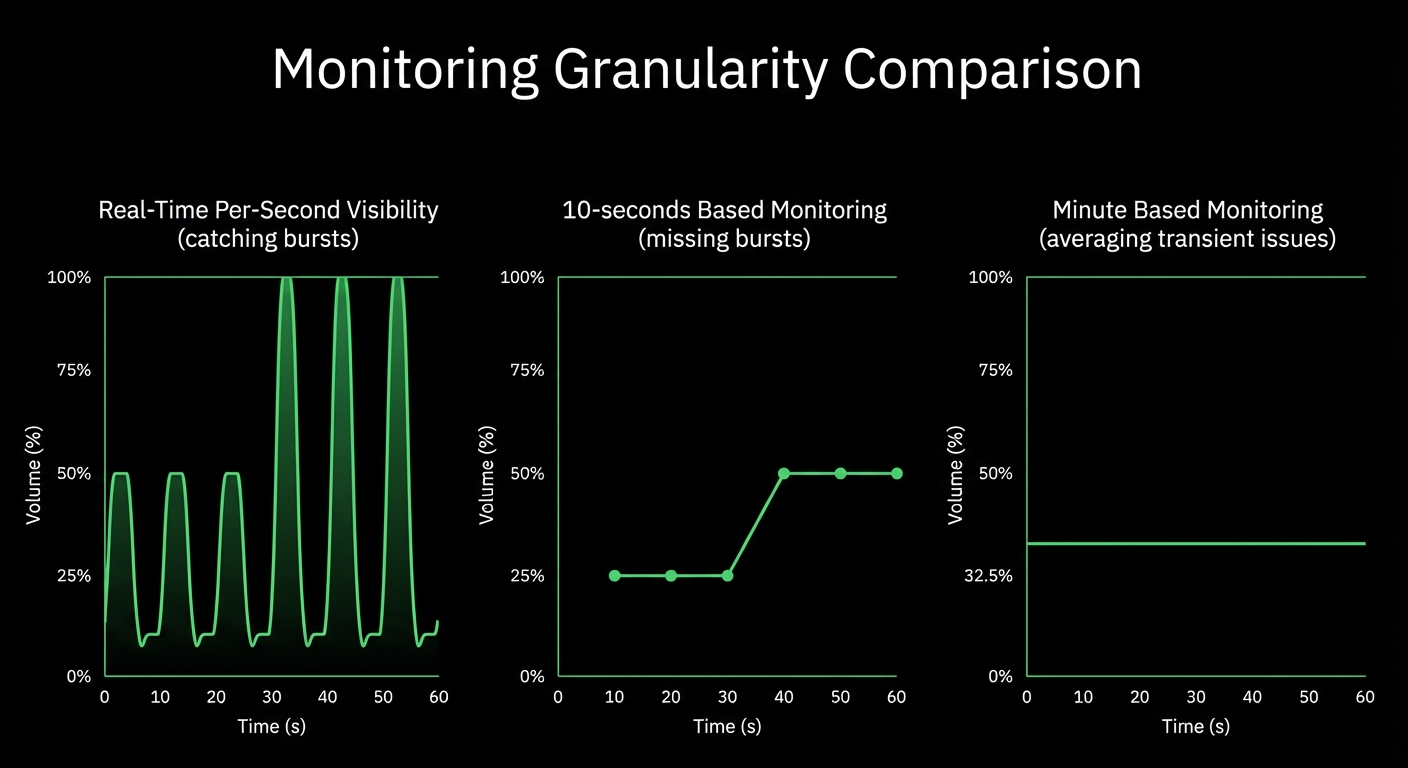
Traditional monitoring misses 90% of HPC incidents because they happen in seconds, not minutes. Netdata’s per-second granularity captures GPU throttling, memory bursts, and network microbursts as they occur - giving your team the visibility to prevent cascading failures before they impact research outcomes.

Built for the Speed of Science
Six capabilities that transform HPC operations
True Real-Time Visibility
Sub-2-second latency from event to insight. Capture GPU throttling, memory spikes, and network bursts that 30-second monitoring completely misses.
ML-Powered Anomaly Detection
18 models per metric achieve 99% false positive reduction. Automatically correlate anomalies across thousands of metrics to surface root causes in seconds.
Deploy in 60 Seconds
Zero configuration required. Auto-discovers GPUs, InfiniBand, containers, and jobs. Algorithmic dashboards generate instantly - no PromQL, no manual setup.
Edge-Native Architecture
Process data where it’s generated. Linear scalability to 100,000+ nodes with <5% CPU overhead. No centralized bottlenecks, no data egress costs.
90% Cost Reduction
Predictable per-node pricing with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers. Industry-leading 0.6 bytes/sample compression delivers 15× longer retention than alternatives.
Production-Ready Security
SOC 2 Type 2 certified with data sovereignty by design. NIST-aligned multi-zone architecture keeps sensitive research data on-premises.
Trusted by research institutions and HPC centers worldwide





Solve the Challenges That Hold Back HPC Operations
Capture Transient Events Before They Cascade
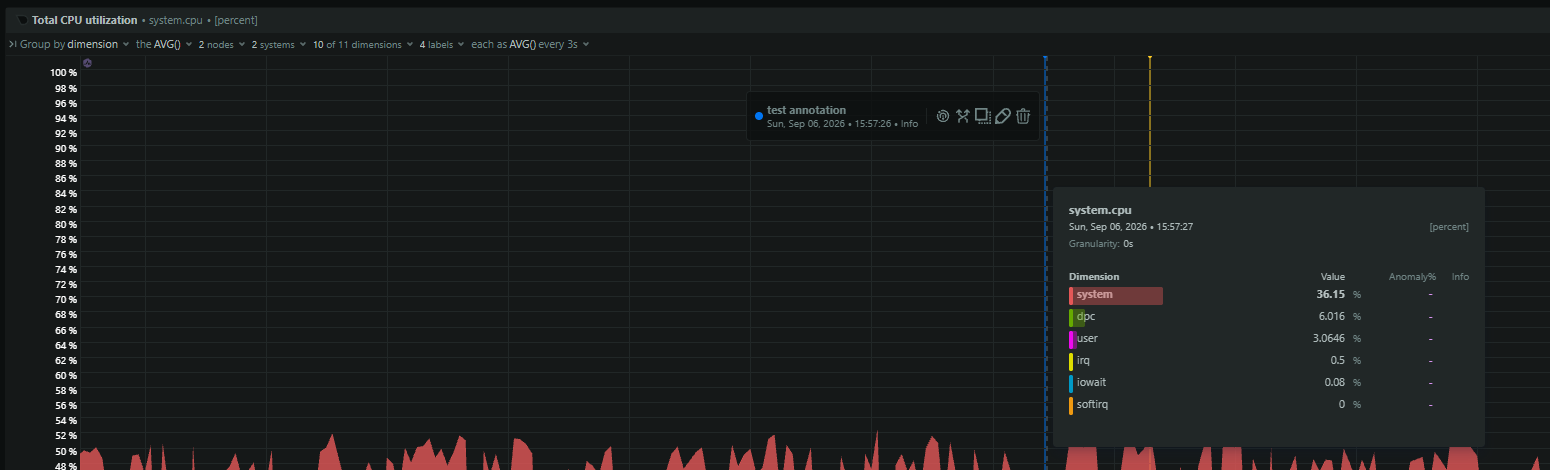
16× faster queries than Prometheus
See Real-Time Performance

Accurate Anomaly Detection With Multi-Model Consensus
99% false positive reduction in anomaly detection
Explore ML Capabilities


Monitor GPU Clusters Without DCGM Headaches
Multi-vendor GPU support
View GPU Monitoring


See InfiniBand Traffic That Kernel Bypass Hides
Native RoCE/RDMA monitoring
Learn About Network Monitoring


Correlate Jobs With Infrastructure Automatically
Per-second job-level metrics
See Job Monitoring


Troubleshoot Without SSH Access
Console replacement
Explore Netdata Functions


Why HPC Teams Choose Netdata
Built for HPC, Not Adapted From IT Monitoring
Traditional monitoring tools were designed for enterprise IT - not the microsecond-level precision and extreme scale of HPC environments. See how Netdata’s purpose-built architecture delivers what research computing demands.
Capability
Netdata
Traditional Monitoring
Data Granularity
Time resolution for metric collection
✅ Per-Second
Captures transient GPU throttling and memory spikes
⚠️ Per-Minute
Misses 90% of HPC incidents under 10 seconds
Total Latency
Event to insight visibility
✅ Sub-2 Seconds
Interactive troubleshooting during live incidents
❌ 30-120 Seconds
Delayed visibility prevents rapid response
GPU Monitoring
Multi-vendor accelerator support
✅ DCGM-Free
Avoids production failures via nvidia-smi direct
⚠️ DCGM-Dependent
Inherits connection failures and MIG issues
InfiniBand Visibility
High-speed interconnect monitoring
✅ Native RoCE/RDMA
Hardware counters for congestion and errors
❌ Limited or None
Kernel bypass prevents standard monitoring
Job-Level Metrics
Per-job resource tracking
✅ Native Cgroups
Automatic per-second CPU, memory, I/O, network
⚠️ Manual Integration
Requires separate exporters and correlation
ML Anomaly Detection
Automated issue identification
✅ 18-Model Consensus
99% false positive reduction in anomaly detection
⚠️ Basic or None
Manual threshold tuning or external ML required
Configuration Required
Time to operational monitoring
✅ Zero Config
Auto-discovery, algorithmic dashboards, 60 seconds
❌ Extensive Setup
Manual exporters, dashboard building, days to weeks
Storage Efficiency
Bytes per metric sample
✅ 0.6 Bytes/Sample
15× longer retention on same disk
⚠️ 2-16 Bytes/Sample
Higher storage costs, shorter retention
Scalability Model
Performance at 10,000+ nodes
✅ Linear Scaling
Proven 100,000+ nodes, distributed architecture
⚠️ Federation Required
Complex clustering, performance degradation
Pricing Model
Cost structure and predictability
✅ Predictable Per-Node
Per-node pricing, no per-metric charges
❌ Volume-Based
Per-metric charges, unpredictable bills
Purpose-Built for HPC Workloads
Multi-Vendor GPU Monitoring Without DCGM Dependencies
Monitor NVIDIA, AMD, and Intel GPUs with per-second granularity. Capture utilization, memory, temperature, power, PCIe bandwidth, and thermal throttling events - without DCGM connection failures or MIG incompatibility issues.
DCGM-free reliability
Explore GPU Monitoring


Why Research Computing Teams Choose Netdata
Purpose-built capabilities that transform HPC operations
Capture Transient Events
Per-second granularity reveals GPU throttling, memory spikes, and network bursts that minute-based monitoring completely misses - critical for understanding cascading failures.
Accurate Anomaly Detection
18-model ML consensus achieves 99% false positive reduction in anomaly detection. Anomaly Advisor automatically correlates anomalies across thousands of metrics to surface root causes.
Deploy in 60 Seconds
Zero configuration required. Auto-discovers infrastructure, generates algorithmic dashboards, and starts ML training automatically - operational visibility in one minute.
Scale Without Limits
Distributed edge-native architecture scales linearly to 100,000+ nodes with <5% CPU overhead. No centralized bottlenecks, no architectural rewrites as you grow.
Predictable Economics
Predictable per-node pricing with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers. Industry-leading compression delivers 15× longer retention - 90% cost reduction versus commercial alternatives.
Production-Ready Security
SOC 2 Type 2 certified with data sovereignty by design. NIST-aligned multi-zone architecture keeps sensitive research data on-premises where it belongs.
InfiniBand Visibility
Native monitoring of RoCE/RDMA operations, congestion notifications, and hardware errors - visibility that kernel bypass prevents standard tools from capturing.
Intelligent Correlation
Automatic anomaly correlation across infrastructure and jobs. Reveals cascading failure sequences and blast radius - 80% MTTR reduction through rapid root cause identification.
Console Replacement
Browser-based access to processes, network connections, logs, and I/O - all with history and ML anomaly detection. Secure troubleshooting without SSH access.

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.

October 3, 2026
Who Built This Dashboard, and Are They Still Here?
Your server monitoring dashboard shouldn't be a DIY project. Netdata charts every metric automatically — no query languages, no dashboards to build, ever.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.