





 Kubernetes Monitoring
See Every Second of Your Kubernetes Infrastructure
Per-second visibility across control plane, nodes, pods, and containers. ML-based anomaly detection on every metric from day one. AI-powered troubleshooting that explains what broke and why - in plain English. All at 90% lower cost than traditional monitoring.

Why Kubernetes Teams Choose Netdata
The only monitoring platform built for real-time Kubernetes observability at scale
80% Faster MTTR
Per-second metrics catch microbursts others miss. ML-powered Anomaly Advisor surfaces root cause in top 30-50 results. AI Co-Engineer explains issues in plain English.
90% Cost Reduction
Predictable per-node pricing for infrastructure monitoring, with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers. Billed per node, with no per-pod charges. No cardinality penalties. No surprise bills.
Zero Configuration
Install in 60 seconds. Automated dashboards, 400+ pre-configured alerts, and ML anomaly detection work immediately - no query languages, no manual setup.
True Real-Time
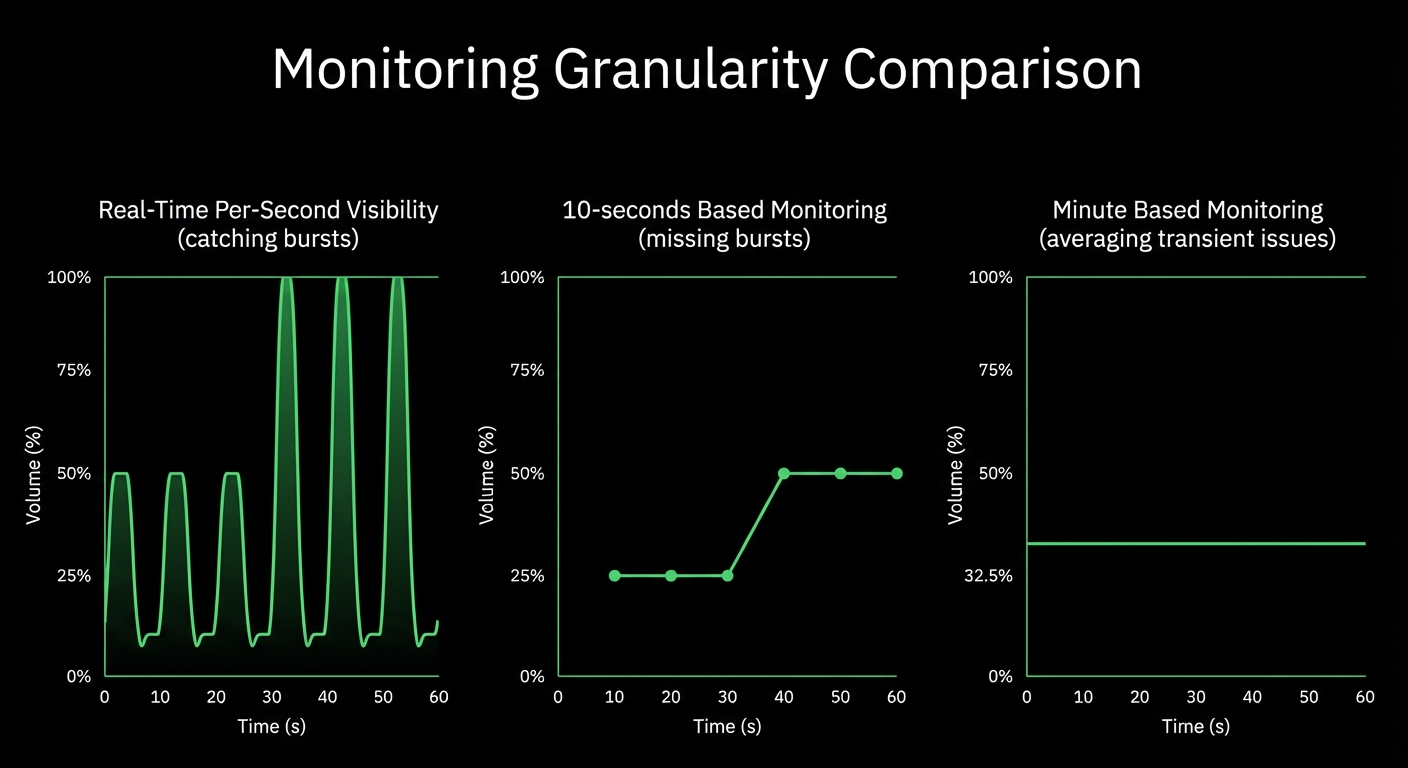
1-second data collection and visualization latency. Catch 2-10 second anomalies invisible to minute-based monitoring. See problems as they happen, not after.
ML on Every Metric
18 unsupervised models per metric trained at the edge. 99% false positive reduction through consensus detection. Works day one - no months of training required.
Edge-Native Intelligence
Data stays on-premises. ML runs locally. No cloud dependency. Complete data sovereignty. Works offline. Scales linearly to unlimited clusters.
Trusted by DevOps teams worldwide












Why Kubernetes monitoring bills explode
Most Kubernetes monitoring tools were designed for hosts. Then operators put them on K8s and the bill arrived.
Per-host SaaS pricing on Kubernetes
Each node is billed; each pod is billed; each container often counts too.
Bills compound with pod density, not service value
A team running 200 pods on 20 nodes is billed as if it’s running 200 hosts.
Cardinality explosion from pod label sets
Every pod adds labels like pod_name, pod_uid, replica_set — high-cardinality by design.
Custom-metric pricing punishes label-rich workloads
Operators learn to drop labels they actually need during incidents.
Polling-based collectors on short-lived pods
A pod that lives 90 seconds may never be scraped by a 60-second-interval collector.
Per-pod metrics that just… aren’t there during incidents
The OOMKilled pod’s last 45 seconds are invisible to forensics.
Built for Modern Kubernetes Operations
Complete Control Plane Visibility
100% sample completeness
Learn about control plane monitoring

Node and Pod Health at Scale
<5% CPU overhead
Explore infrastructure monitoring

Logs Without Pipelines
90% cost savings
Discover logs management

Trace Requests Across Pods
Metrics, logs and traces
Explore distributed tracing


AI-Powered Root Cause Analysis
80% MTTR reduction
See AI troubleshooting

Multi-Cluster at Scale
Linear scalability
Learn about scalability

Cost Visibility and Control
Predictable pricing
View pricing
Netdata vs Traditional Kubernetes Monitoring
Why Kubernetes Teams Switch to Netdata
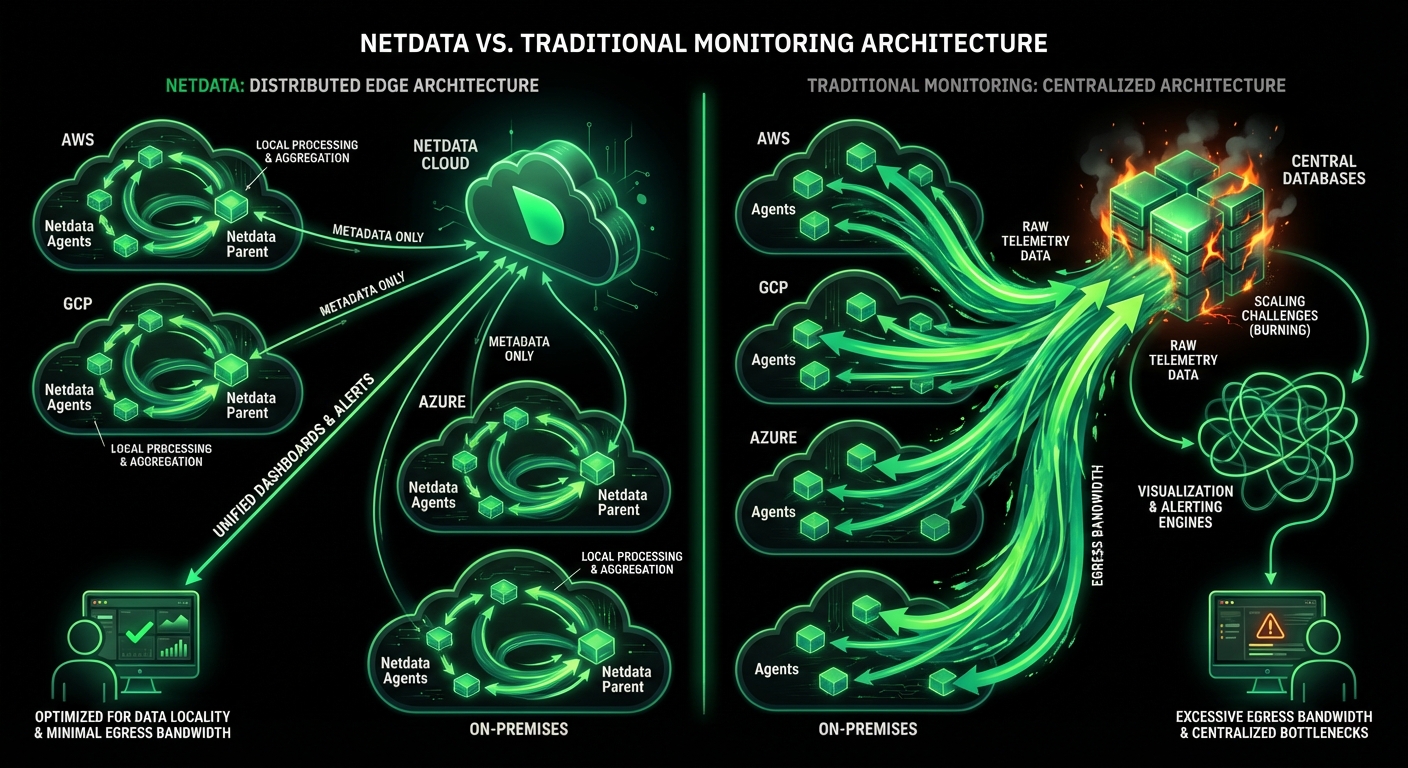
Traditional monitoring tools weren’t built for Kubernetes’ dynamic, ephemeral nature. Netdata’s edge-native architecture solves the fundamental challenges of container orchestration at scale.
Capability
Netdata
Traditional Monitoring
Data Granularity
✅ Per-Second
Catches 2-10 second anomalies others miss
⚠️ Per-Minute
Averages hide microbursts and transients
Time to Value
✅ 60 Seconds
Install to full visibility instantly
⚠️ Days to Weeks
Complex setup and configuration required
Cost Model
✅ Per-Node Flat Rate
No per-metric or per-container charges
❌ Multi-Dimensional
Per-host plus data volume plus event charges
ML Anomaly Detection
✅ Day One
18 models per metric, works immediately
⚠️ Months Later
Requires training data before useful
Query Language
✅ None Required
Point-and-click NIDL framework
❌ PromQL/LogQL
Steep learning curve for teams
Dashboard Creation
✅ Automatic
Algorithmic generation based on data
❌ Manual Build
Hours to weeks of configuration
Alert Configuration
✅ 400+ Pre-Built
Component-level, intelligent thresholds
⚠️ Build from Scratch
Manual threshold tuning required
Data Sovereignty
✅ On-Premises
All data stays local, GDPR aligned
❌ Cloud Egress
Metrics, logs and traces leave infrastructure
Control Plane Access
✅ All Components
API server, etcd, scheduler, controller
⚠️ Limited on Managed
EKS/GKE/AKS restrict access
Storage Efficiency
✅ 0.6 bytes/sample
Years of data in gigabytes
⚠️ 2-16 bytes/sample
Terabytes for same retention
Multi-Cluster Support
✅ Unlimited Clusters
Distributed architecture, linear scaling
⚠️ Complex Federation
Requires Thanos/Cortex setup
Container Pricing
✅ Billed Per Node
No per-container (per-pod) charges
❌ Per-Container Charges
Costs scale with pod count
Kubernetes Monitoring That Works
Catch Problems Before They Cascade
Per-second metrics reveal microbursts, transients, and cascading failures invisible to minute-based monitoring. See the exact sequence of events - not averaged approximations.
1-second collection and visualization
Learn about real-time monitoring


Everything You Need for Kubernetes
Comprehensive observability from control plane to containers - all in one platform
Control Plane Monitoring
API server, etcd, scheduler, and controller manager metrics with per-second precision and ML anomaly detection.
Node Health Tracking
CPU, memory, disk, network, and node conditions across thousands of nodes with automated correlation.
Pod and Container Metrics
Restart counts, OOMKilled events, probe failures, resource throttling, and lifecycle tracking.
Logs Without Pipelines
Netdata queries systemd-journal in place and collects pod and container logs through its OpenTelemetry logs pipeline, eliminating Fluentd and Elasticsearch. 90% cost reduction validated.
Intelligent Alerting
400+ pre-configured alerts with intelligent thresholds. Component-level alerting reduces noise automatically.
Anomaly Detection
18 ML models per metric trained at the edge. 99% false positive reduction through consensus detection.
AI Troubleshooting
Natural language investigations. AI explains what broke and why in plain English with recommended actions.
Multi-Cluster Support
Distributed architecture scales to unlimited clusters. Unified view via Netdata Cloud with sub-second queries.
Data Sovereignty
All metrics, logs and traces stay on your infrastructure. Supports GDPR, HIPAA, PCI DSS programs. SOC 2 Type 2 certified.
May 2, 2023
Linux CPU Consumption, Load & Pressure Explained
Understand Linux CPU consumption, load, and pressure metrics, and learn how to read them for smarter performance optimization. Read the full guide now!

May 2, 2023
Server Uptime Monitoring: Core Benefits For High Performance
Track server health & reduce downtime with Netdata’s real-time uptime monitoring. Optimize performance & improve system reliability with ease. Learn more!
May 20, 2022
Monitoring without Cooperation: Kubernetes
Learn how to monitor Kubernetes workloads without direct cooperation from applications. Gain insights with zero-code changes. Read the full guide now!