





 Netdata Parents
Scale Your Infrastructure Without Scaling Your Observability Bill
Intelligent workload distribution that makes your infrastructure lighter, not heavier. Handle million metrics per second with predictable per-node economics, active-active clustering for resilience, and ML-powered insights without centralized bottlenecks.

Why Operations Teams Choose Netdata Parents
Centralize visibility without centralizing overhead
Million Metrics Per Second
Handle 1M metrics/second with just 10 cores and 40GB RAM. Linear scalability from 100 to 10,000 nodes without architectural changes.
Predictable Economics
Per-node pricing scales with infrastructure growth, not metrics volume. No charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers, and no surprise bills.
Distributed ML Intelligence
Train 18 unsupervised models per metric at the edge. First parent trains, others reuse - high availability without duplicate work.
True Real-Time at Scale
Per-second data collection with sub-2-second latency across thousands of nodes. See problems as they happen, not minutes later.
Active-Active Clustering
Multiple parents share intelligence and provide automatic failover. Survive parent failures without losing visibility or duplicating resources.
Intelligent Offloading
Reduce production system overhead by 50% while maintaining complete visibility. Parents handle ML, storage, and alerts - agents stay lean.
Trusted by operations teams worldwide






Transform How You Scale Observability
Offload Everything Heavy, Keep Everything Fast
50% CPU Reduction
Learn About Offloading

Handle Enterprise Scale With Minimal Resources
1M Metrics/Second
See Performance Benchmarks

Achieve High Availability Without Double-Spend
Zero Data Loss
Explore Clustering

Store Years of History in Gigabytes, Not Terabytes
0.6 Bytes/Sample
Learn About Storage

See How Netdata Parents Compare
Intelligent Centralization vs Traditional Approaches
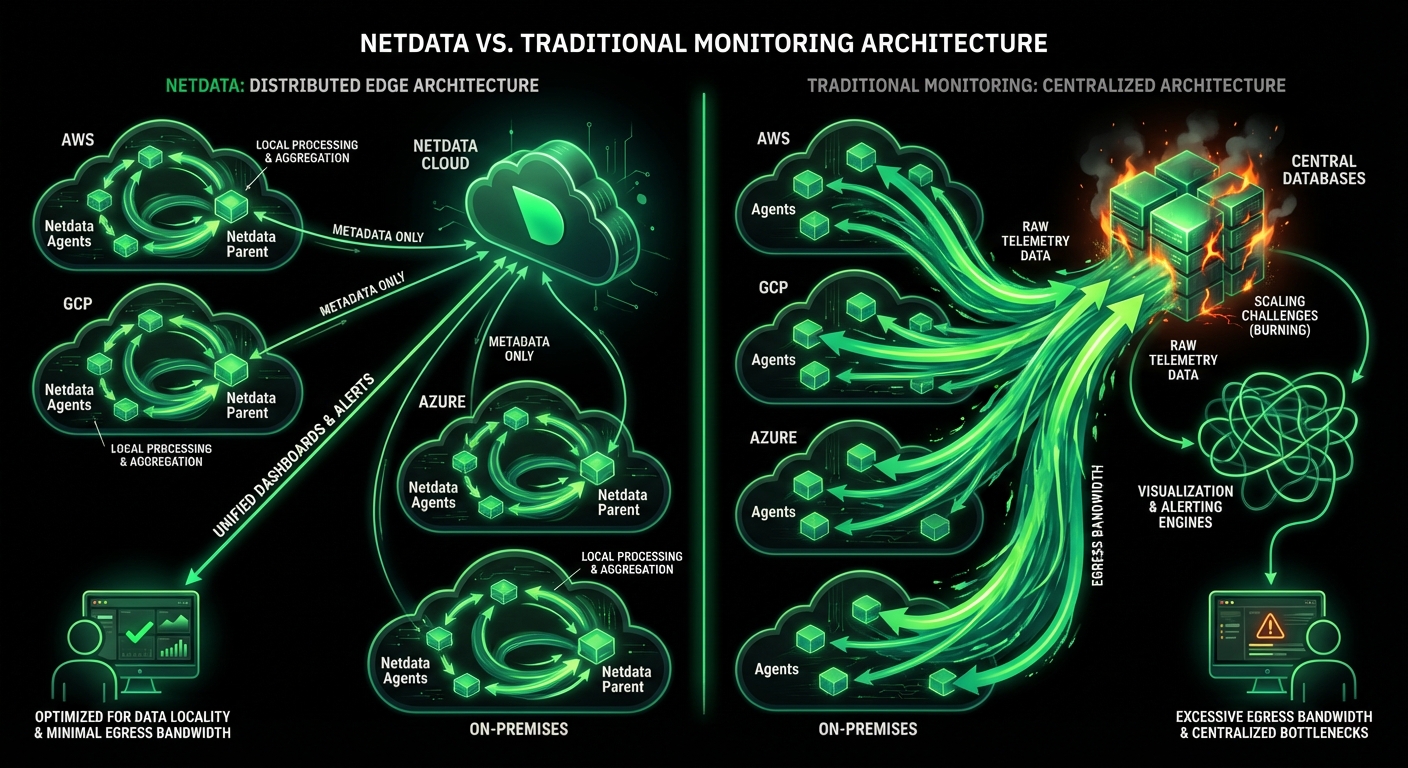
Netdata Parents deliver enterprise-grade capabilities with resource efficiency and predictable economics that traditional solutions cannot match.
Capability
Netdata Parents
Traditional Monitoring
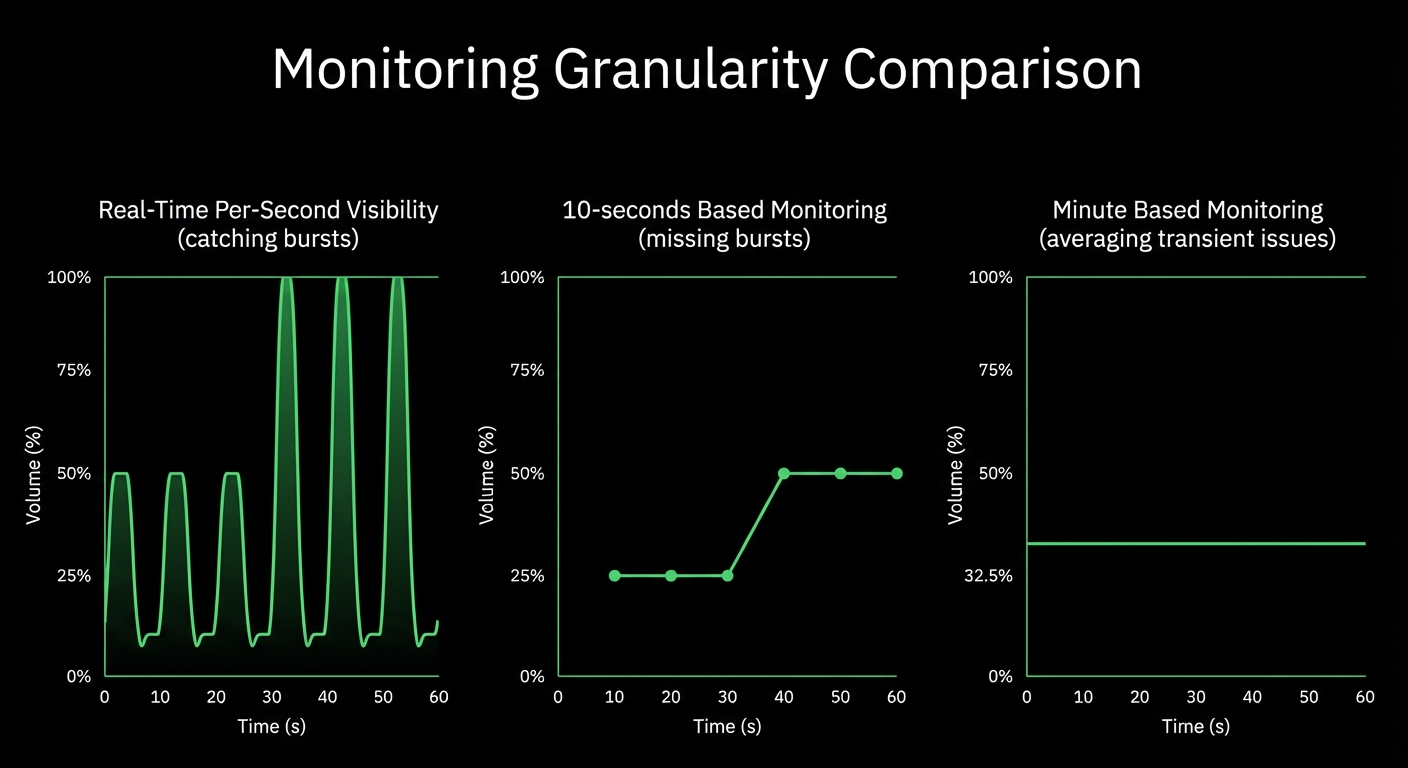
Data Collection
✅ Per-Second
True real-time across all nodes
⚠️ Per-Minute
Averaged data misses transient issues
Resource Efficiency
✅ Ideal
Lowest CPU and RAM overhead validated
⚠️ Basic
Higher overhead on production systems
ML Anomaly Detection
✅ Advanced
18 models per metric, edge-trained
⚠️ Limited
Requires external platforms or manual setup
High Availability
✅ Included
Active-active clustering with intelligent work sharing
⚠️ Complex
Requires external HA solutions and configuration
Configuration Burden
✅ Automated
Zero-config discovery and algorithmic dashboards
⚠️ Manual
Extensive YAML files and target configuration
Pricing Model
✅ Simple
Per-node with volume discounts
❌ Complex
Per-metric, per-log, per-feature charges
Storage Efficiency
✅ Advanced
0.6 bytes/sample, multi-tier architecture
⚠️ Basic
2-16 bytes/sample, single-tier storage
Query Performance
✅ Real-Time
Sub-2-second latency at any scale
⚠️ Near Real-Time
Minutes of latency under load
Data Sovereignty
✅ Included
All data stays on-premises
⚠️ Limited
Often requires vendor cloud or complex self-hosting
How Netdata Parents Work
Real-Time Push With Zero Data Loss
Agents stream metrics to parents continuously via push-based architecture. Automatic buffering during disconnections ensures zero data loss. Historical replication synchronizes complete data when connectivity restores.
2-5M samples/second per replication thread
Learn About Streaming


Key Benefits of Netdata Parents
Centralize visibility without centralizing overhead
Linear Scalability
Add nodes without degrading performance. Same architecture from 100 to 10,000 nodes without redesign.
Predictable Economics
Per-node pricing scales with infrastructure growth, not metrics volume. No overage charges or surprise bills.
Production Resilience
Active-active clustering with automatic failover. Monitoring survives parent failures without losing visibility.
Resource Optimization
Offload heavy work to parents. Reduce production system overhead by 50% while maintaining complete visibility.
Distributed Intelligence
ML trains at edge or parents. Models flow with metrics - train where convenient, use everywhere.
True Real-Time
Per-second collection with sub-2-second latency across thousands of nodes. See problems as they happen.
Complete Autonomy
Agents operate independently during disconnections. Automatic replication when connectivity restores.
Unified Visibility
Single-pane infrastructure view without centralizing data. Query distributed agents through parents.

May 30, 2026
High Cardinality Metrics At Scale: A Better Playbook
Discover why the standard high-cardinality playbook is wrong and how to handle metrics at scale without ballooning costs. Read the full guide now!
December 1, 2025
Monitor Everything is an Anti-Pattern!
The industry says 'monitor everything' is bad. But the same industry keeps discovering monitoring gaps during outages. What's really going on?

January 23, 2025
Netdata vs Prometheus: A 2025 Performance Analysis
Netdata 2.2 vs Prometheus 3.1 performance analysis. A Deep Dive into Performance, Efficiency, and Scalability