



 Our Core Philosophy
Engineering Excellence for Operational Simplicity
At Netdata, we invest engineering work to eliminate complexity, not manage it. We profit by simplifying operations - not by charging for data movement, storage, or processing volume. These 12 principles guide every technical and product decision we make, representing our commitment to the world’s operations teams who manage increasingly complex infrastructures with lean teams and limited resources.
What Drives Us
Six core values that define how we build and deliver observability
Radical Transparency
Open source foundation, verifiable performance claims, honest pricing. What you see is what you get - always.
Your Data, Your Control
Complete data sovereignty by design. Your infrastructure’s secrets stay yours, supporting your compliance programs.
Truth Over Averages
Per-second reality reveals what minute-averaging hides. See actual system behavior, not statistical fiction.
Intelligence Without Complexity
Expert-level visibility for every engineer. Zero configuration, algorithmic dashboards, ML-powered insights.
Freedom to Choose
No lock-in by design. Open standards, open source, bring-your-own-LLM. Your future stays open.
Honest Economics
Transparent per-node pricing. We profit by making monitoring better, not by charging for metrics volume.
Trusted by operations teams worldwide






The 12 Netdata Principles
Your Infrastructure, Your Data, Your Control
Why This Matters: GDPR, HIPAA, PCI DSS programs are supported because metrics never leave your infrastructure. No vendor lock-in, no surprise egress charges, no monitoring data stored by a vendor. Monitoring continues working even during internet outages.
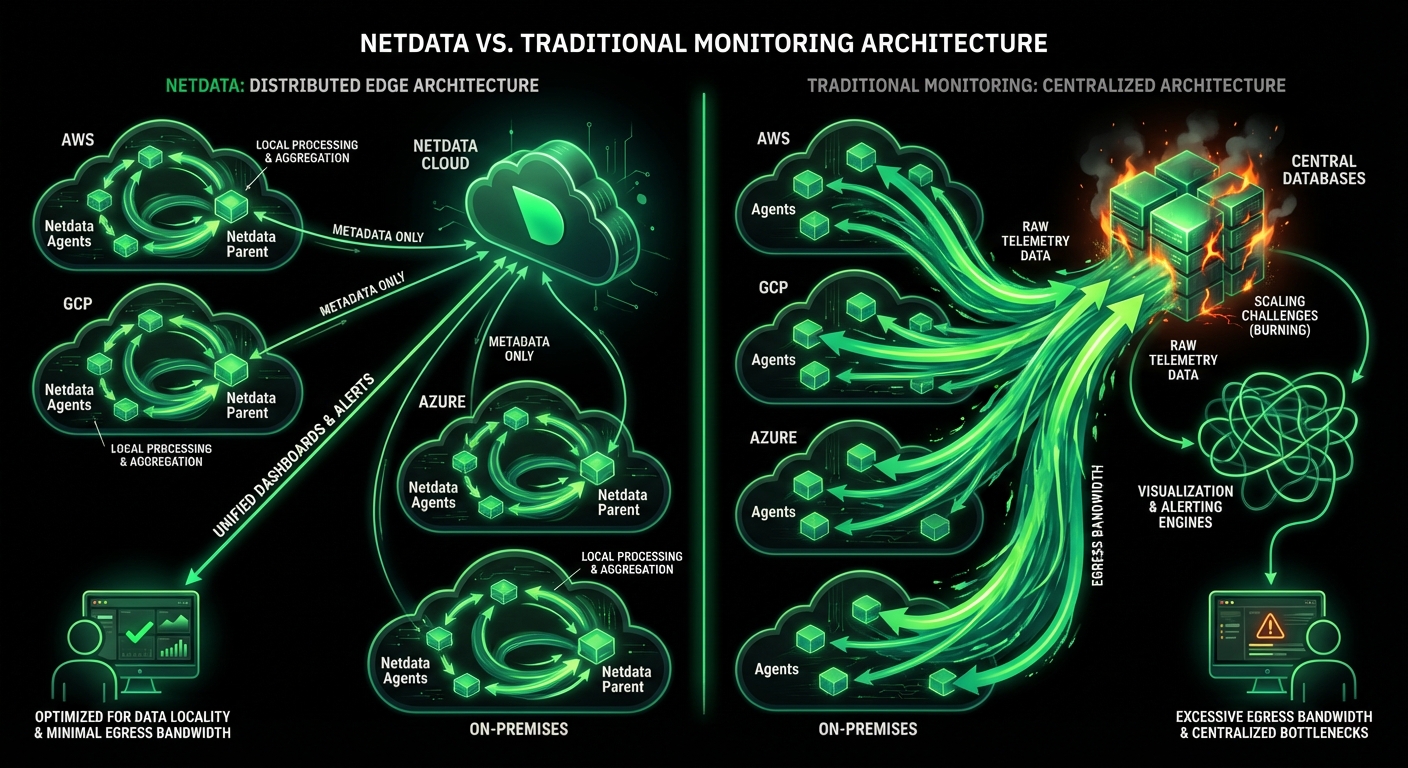
How We Deliver: Distributed architecture keeps all data local. Only metadata travels to Netdata Cloud. Machine learning trains locally. On-premises deployment for air-gapped environments. You choose where data lives.
The Innovation: While others centralize your data and charge for it, we distribute intelligence to your systems and let you keep what’s yours.
100% Data Sovereignty
Learn About Data Sovereignty


Real-Time Means Per-Second, Not Near Real-Time
Why This Matters: Most operational anomalies last 2-10 seconds. With 30-second monitoring, you’re blind to 90% of incidents. A 3-second CPU spike can trigger a 30-second outage if not detected immediately. Security threats happen in seconds - port scans, crypto-miners, memory attacks invisible to minute-based tools.
How We Deliver: 1-second data collection across all 800+ integrations. 1-second visualization latency. Sub-2-second worst-case total latency. No sampling, no averaging, no statistical approximations. Gaps in charts reveal system stress - if Netdata can’t collect, your applications can’t serve.
The Innovation: We proved sustained per-second monitoring at scale is achievable and essential. Independent testing shows lowest resource overhead while providing 10-60× faster insights than traditional solutions.
Sub-2-Second Latency
Explore Real-Time Architecture


Zero Configuration, Instant Value
Why This Matters: Eliminate setup time - no weeks spent configuring collectors or building dashboards. Reduce operational burden - infrastructure changes don’t require monitoring updates. Democratize observability - junior engineers get same powerful tools as senior SREs without specialized training. Focus on problems, not tools.
How We Deliver: Auto-discovery detects systems, containers, applications automatically. Algorithmic dashboards generate based on data’s semantic meaning. Universal navigation - same logical structure across all infrastructures. Point-and-click analysis without knowing metric names. 1,100+ pre-configured alerts work out-of-the-box. ML-based anomaly detection starts automatically after 15 minutes of baseline data collection and reaches full confidence in 2 days.
The Innovation: Dashboards are an algorithm, not a configuration. Each chart is a complete analytical tool equivalent to 25+ Grafana charts, providing 360° views with simple point-and-click.
One-Line Install to Insights
See Zero Configuration in Action

Intelligence at the Edge, Not in the Cloud
Why This Matters: Linear scalability - adding 100 nodes costs and performs the same as the first 100. No central bottlenecks - each agent operates independently. Faster insights - no round-trip to cloud for analysis. Lower costs - no bandwidth charges for streaming terabytes. Resilient operation - monitoring continues during network partitions. Privacy by design - sensitive data never leaves infrastructure for ML processing.
How We Deliver: Complete observability engine per agent - collects, stores, analyzes, detects anomalies, checks alerts, serves dashboards independently. Edge-based machine learning - 18 unsupervised models per metric train locally. Distributed correlation - real-time anomaly correlation across all metrics. Parent-child streaming with automatic failover. Horizontal scaling - deploy more parents without complex sharding.
The Innovation: Each Netdata Agent is a full monitoring system, not just a data forwarder. This distributed architecture processes 4.5+ billion metrics/second globally while maintaining sub-2-second latency.
4.5B+ Metrics/Second
Understand Edge Architecture

Monitor Everything, Miss Nothing
Why This Matters: Eliminate blind spots - the metric you didn’t think to collect often holds the answer during incidents. Resolve the prediction paradox - if you could predict what will break, you’d prevent it. Enable ML effectiveness - algorithms find correlations across unrelated metrics that humans miss. Reduce MTTR - all data available immediately during investigations. Support skill independence - junior engineers get same comprehensive visibility as senior staff.
How We Deliver: 800+ integrations for systems, containers, VMs, hardware, databases, web servers, message brokers, cloud services. Universal protocols - OpenTelemetry, OpenMetrics, StatsD, SNMP, custom collectors. Hierarchical organization - 50 disk metrics stay in disk section, 100 container metrics in container view. Unlimited cardinality - high-cardinality data handled without performance degradation.
The Innovation: We proved comprehensive monitoring is more efficient than selective monitoring. University of Amsterdam study confirmed Netdata is the most energy-efficient monitoring solution despite collecting everything, every second.
800+ Integrations
Browse All Integrations

Efficiency Through Engineering, Not Through Compromise
Why This Matters: Lower infrastructure costs - minimal CPU, RAM, and disk I/O per agent. Sustainable at scale - 500 nodes with 2M metrics/second requires only 20 cores and 80GB RAM for parent cluster. No performance tax - monitoring doesn’t compete with applications for resources. Environmental responsibility - most energy-efficient monitoring solution with peer-reviewed validation. Predictable resource usage - stable consumption patterns without sudden spikes.
How We Deliver: Industry-leading compression - 0.6 bytes per sample enables years of retention in gigabytes. Write-once storage - append-only files with no compaction or maintenance windows. Multi-tier architecture - three resolution tiers updated in parallel. Spread workload - data commits every 17 minutes, spread evenly over time. Efficient ML - unsupervised k-means runs as low-priority background tasks.
The Innovation: Netdata benchmark shows 37% less CPU, 88% less RAM, 97% less disk I/O than Prometheus - while providing 15× longer per-second retention and 22× faster large queries.
0.6 Bytes/Sample
See Performance Benchmarks


Transparent Economics: Nodes, Not Metrics Volume
Why This Matters: No surprise bills - costs scale linearly with infrastructure, not with metrics volume spikes. Collect without anxiety - no penalties for high-resolution metrics, custom metrics, or deep cardinality. Budget predictability - simple per-node pricing enables accurate financial planning. Core monitoring on every plan - ML anomaly detection, alerting and dashboards. Align incentives - we profit by making monitoring better, not by charging for metrics volume.
How We Deliver: Per-node pricing with predictable costs and volume discounts. No per-metric charges - custom metrics, dimensions, and cardinality don’t change the bill. No per-seat charges - team collaboration without per-user fees. Core capabilities not gated - ML anomaly detection, AI insights, alerting, dashboards. Homelab pricing - affordable yearly rate for personal non-commercial use.
The Innovation: While others charge based on data volume forcing you to choose between visibility and cost, we charge based on infrastructure size - aligning our success with your operational needs.
90% Cost Reduction
Compare Pricing Models


Open Standards, No Lock-In
Why This Matters: Freedom to choose - integrate with existing tools or switch solutions without data migration nightmares. Protect investments - existing instrumentation works without changes. Avoid dependency - no proprietary query languages or data formats that trap you. Community innovation - open-source foundation enables customization and contributions. Future-proof architecture - standards-based approach adapts to evolving technology landscape.
How We Deliver: Open-source core - 80,000+ GitHub stars, 1.5M daily downloads, community validation. Standards support - OpenTelemetry, Prometheus, OpenMetrics, StatsD. Open log formats - systemd-journal, Windows Event Log, industry standards. Grafana integration - native datasource plugin preserves existing investment. Export flexibility - Prometheus, InfluxDB, Graphite, OpenTSDB, TimescaleDB supported.
The Innovation: We built the most advanced monitoring platform on open standards and open-source foundations, proving you don’t need vendor lock-in to deliver exceptional value.
80K+ GitHub Stars
Explore Open Source

Troubleshooting First, Dashboards Second
Why This Matters: Proactive detection - learn about problems from Netdata before customers complain. Faster resolution - 80% reduction in MTTR through immediate visibility and ML-powered root cause analysis. Console replacement - debug without SSH, all console tools unified in browser with history. Accurate ML detection - 18-model consensus achieves 99% false positive reduction in anomaly detection. Contextual insights - Anomaly Advisor surfaces the 30-50 metrics that matter during incidents.
How We Deliver: Real-time anomaly detection - ML runs during data collection, not in batch jobs. Correlation engine - automatically identifies related anomalies across metrics. Blast radius detection - visualizes impact spread in real-time. Cascading failure analysis - shows exact sequence of which component failed first and why. AI troubleshooting - one-click Ask AI on every alert for instant context and recommended actions. Live system state - processes, network connections, systemd units, all with history and ML.
The Innovation: We transformed monitoring from what happened to what’s wrong and how to fix it - with ML and AI providing answers in seconds, not hours.
80% MTTR Reduction
See Troubleshooting in Action


Logs Without Pipelines, Queries Without Servers
Why This Matters: 90% cost reduction - eliminate Elasticsearch/Splunk infrastructure and storage multiplication; Logs Monitoring (querying logs in place) is not billed. No data loss - keep all logs without sampling or filtering to manage costs. More accurate on large journals - fully evaluates the first 500,000 entries of a query, then samples up to 1M. Instant correlation - logs and metrics from same source, no timestamp matching or separate systems. Compliance support - systemd-journal Forward Secure Sealing for journal tamper detection, data stays at edge for GDPR/sovereignty.
How We Deliver: Direct file access - clients open journal files directly, no query servers needed. Comprehensive indexing - every field in every log entry automatically indexed by journald. Flexible schema - each entry can have unique fields, all fully searchable. Native tooling - built-in centralization, filtering, exporting via systemd-journal-upload. Log transformation - log2journal converts text/JSON/logfmt into structured, indexed entries. Windows support - full Windows Event Logs, ETW, and TraceLogging, unified logging across platforms. Any other source - Logs Management collects files, syslog, Kubernetes, application and cloud logs through the OpenTelemetry Collector into Netdata’s log store, with every field indexed.
The Innovation: Instead of copying every log to expensive centralized systems, we built better tools on the robust foundation already present in every system, and centralize only the logs that need it in Netdata’s own log store - eliminating needless data movement while delivering superior capabilities.
90% Cost Savings
Learn About Zero-Pipeline Logs


AI That Understands Your Infrastructure
Why This Matters: Democratize expertise - junior engineers operate at senior-level effectiveness with AI guidance. Accelerate resolution - AI explains alerts in plain language with recommended actions. Reduce cognitive load - AI Insights generates professional reports in 2-3 minutes instead of hours of manual analysis. Natural language queries - ask questions about your infrastructure in your language, no query languages required. Continuous learning - ML models adapt to your infrastructure’s unique patterns automatically.
How We Deliver: Embedded ML - 18 unsupervised models per metric train automatically, with first anomaly detection available after 15 minutes of baseline data collection. Anomaly Advisor - cuts through thousands of metrics to show the 30-50 that matter right now. AI Insights reports - infrastructure summary, capacity planning, performance optimization, anomaly analysis, all automated. AI Chat via MCP - ask questions using Claude, ChatGPT, Gemini, or other LLMs with bring-your-own-LLM support. Alert AI - one-click explanations for any alert with context and recommendations. Root cause analysis - correlation engine identifies cascading failures and blast radius automatically.
The Innovation: We embedded AI throughout the platform - from data collection to troubleshooting to reporting - making every engineer more effective regardless of experience level.
18 ML Models/Metric
Explore AI Features


Production-Ready Security by Design
Why This Matters: Compliance confidence - SOC 2 Type 2 certified, GDPR/HIPAA/PCI DSS aligned by design. Reduced risk - security best practices embedded in architecture, not optional add-ons. Audit readiness - comprehensive audit logs and access controls support regulatory requirements. Enterprise authentication - SSO via Okta and OpenID Connect, with automatic role mapping via SCIM. Data protection - metrics, logs and traces never leave infrastructure, only metadata travels to Cloud.
How We Deliver: TLS everywhere - encrypted agent-cloud communication by default. Zero-trust architecture - no implicit trust between components. RBAC - role-based access control with granular permissions. SSO integration - enterprise authentication with Okta and OpenID Connect, plus SCIM user provisioning. Audit logging - comprehensive activity tracking for compliance. Data sovereignty - all observability data stays on-premises under your control. OpenSSF best practices - follows Open Source Security Foundation guidelines.
The Innovation: We built security into the foundation - not as premium features - ensuring every deployment meets enterprise security standards from day one.
SOC 2 Type 2
Review Security Design

How These Principles Work Together
These principles are not isolated features - they form a cohesive philosophy that transforms observability
Edge Architecture + Data Sovereignty
Principles 1 & 4
Linear Scalability + Compliance Support
Scale infrastructure freely without exponential costs or regulatory concerns
Per-Second Granularity + Real-Time ML
Principles 2 & 11
Proactive Detection + Faster Resolution
Catch issues before cascade, resolve incidents 80% faster
Zero Configuration + Complete Coverage
Principles 3 & 5
Eliminate Prediction Paradox
All data available when needed without manual selection
Efficiency Through Engineering + Transparent Pricing
Principles 6 & 7
Predictable Costs + Sustainable Scale
Monitor everything without budget anxiety
Open Standards + Logs Without Pipelines
Principles 8 & 10
Investment Protection + Cost Reduction
Preserve institutional knowledge, eliminate infrastructure overhead
Embedded AI + Security by Design
Principles 11 & 12
Democratized Expertise + Enterprise Readiness
Every engineer effective, every deployment enterprise-ready
The Netdata Difference
How Our Values Translate to Real Benefits
Compare traditional monitoring approaches with Netdata’s values-driven architecture
Capability
Traditional Monitoring
Netdata
Data Location
❌ Centralized
All data sent to vendor cloud
✅ Edge-Native
Data stays on your infrastructure
Pricing Model
❌ Volume-Based
Unpredictable costs scale with data
✅ Per-Node
Transparent pricing, flat rate
Data Granularity
⚠️ Per-Minute
10-60 second intervals miss issues
✅ Per-Second
Sub-2-second latency catches everything
Configuration Required
❌ Extensive
Days to weeks of setup
✅ Zero
Dashboards as soon as data is collected
ML Coverage
⚠️ Selected Metrics
Manual configuration, additional cost
✅ All Metrics
18 models per metric automatically
Vendor Lock-In
❌ Proprietary Formats
Custom query languages trap knowledge
✅ Open Standards
OpenTelemetry, open source foundation
Log Management
❌ Centralized Pipeline
Expensive infrastructure, ingestion fees
✅ Advanced
OS logs queried in place (90% cost savings); any other source collected through OpenTelemetry
AI Integration
⚠️ Vendor-Locked
Proprietary AI, limited LLM choice
✅ Bring-Your-Own
MCP support for any LLM provider
Compliance
⚠️ By Attestation
Requires vendor certifications
✅ By Architecture
Data sovereignty supports compliance
Resource Overhead
⚠️ Moderate to High
10-30% CPU typical
✅ Minimal
Less than 5% CPU, 150 MB RAM (standalone, ML enabled)
Our Commitment to You
These principles represent our commitment to the world’s operations teams
Engineering Over Extraction
We invest engineering effort to eliminate complexity, not manage it. We profit by making monitoring better, not by charging for metrics volume.
Respect Your Data
Your infrastructure’s secrets stay yours. Data sovereignty isn’t a premium feature - it’s a fundamental right built into our architecture.
Transparency Always
Open source code, verifiable performance claims, honest pricing. What you see is what you get - no hidden fees, no surprise bills.
Freedom to Choose
No vendor lock-in through proprietary formats or query languages. Your observability investment should outlast any vendor relationship.
Democratize Expertise
Junior engineers get senior-level visibility automatically. Operations centers maintain consistent quality across all shifts and skill levels.
Align Our Success
When you scale infrastructure, you don’t face exponential monitoring costs. When regulations change, you don’t require architectural rewrites.

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.

October 3, 2026
Who Built This Dashboard, and Are They Still Here?
Your server monitoring dashboard shouldn't be a DIY project. Netdata charts every metric automatically — no query languages, no dashboards to build, ever.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.