



 Netdata vs Prometheus
Troubleshoot Production Issues in Seconds, Not Hours
While Prometheus requires weeks of PromQL training and complex setup, Netdata delivers complete observability in 60 seconds with zero configuration. Get per-second visibility, built-in ML anomaly detection, and AI-powered troubleshooting - without the operational overhead.

Why Teams Choose Netdata Over Prometheus
Solve Prometheus pain points with architectural innovation
60-Second Time to Value
One-line install to complete observability. No YAML configuration, no dashboard building, no PromQL training required.
True Real-Time Visibility
Per-second metrics with sub-2-second latency. Catch transient issues that 15-30 second monitoring completely misses.
Built-In ML & AI
18 ML models per metric detect anomalies automatically. AI Co-Engineer explains root causes in plain English.
Unlimited Horizontal Scale
Linear scaling to 100,000+ nodes without federation complexity. Each agent operates independently.
90% Cost Reduction
Predictable per-node pricing with no charges for metrics volume, Logs Monitoring (querying logs in place), users, data retention or containers. No surprise bills from metrics volume spikes.
Zero Operational Overhead
Self-managing architecture eliminates the 0.5-2 FTE burden of maintaining Prometheus at scale.
Trusted by DevOps teams worldwide




Platform Comparison
Netdata vs Prometheus
How the platforms compare across critical operational dimensions
Capability
Netdata
Prometheus
Data Granularity
✅ Per-second
1-second collection and visualization
⚠️ 15-30 seconds
Default 15s scrape interval
Visualization Latency
✅ Sub-2 seconds
Event to insight worst-case
⚠️ 30-60 seconds
Scrape plus query delays
Setup Complexity
✅ Automated
One-line install, zero config
⚠️ Manual
Days of YAML configuration
Query Language
✅ None Required
Point-and-click NIDL framework
⚠️ PromQL
Weeks to months learning curve
Scalability Model
✅ Linear Horizontal
Unlimited distributed agents
⚠️ Single-Node Ceiling
5-30M series requires federation
Machine Learning
✅ Built-In
18 models per metric, edge-trained
⚠️ External Tools
Requires Red Hat PAD or custom
AI Troubleshooting
✅ Included
AI Co-Engineer, Anomaly Advisor, RCA
❌ Not Available
No native AI capabilities
Logs Management
✅ Native
OS logs in place + any source via OpenTelemetry
❌ Not Supported
Requires Loki or Elasticsearch
Resource Efficiency
✅ <5% CPU, 150-200 MB RAM
University validated most efficient
⚠️ 4-60GB RAM typical
OOM kills from cardinality
Pricing Model
✅ Per-Node
No charges for metrics volume or Logs Monitoring (querying logs in place)
⚠️ Infrastructure + FTE
Hidden operational costs
Data Sovereignty
✅ Complete
All data stays on-premises
✅ Complete
Self-hosted by design
Enterprise Security
✅ SOC 2 Type 2
RBAC, SSO, TLS by default
⚠️ External Required
No native TLS or auth
Experience the Netdata Advantage
Troubleshoot Without SSH Access
80% MTTR Reduction
Explore Netdata Functions
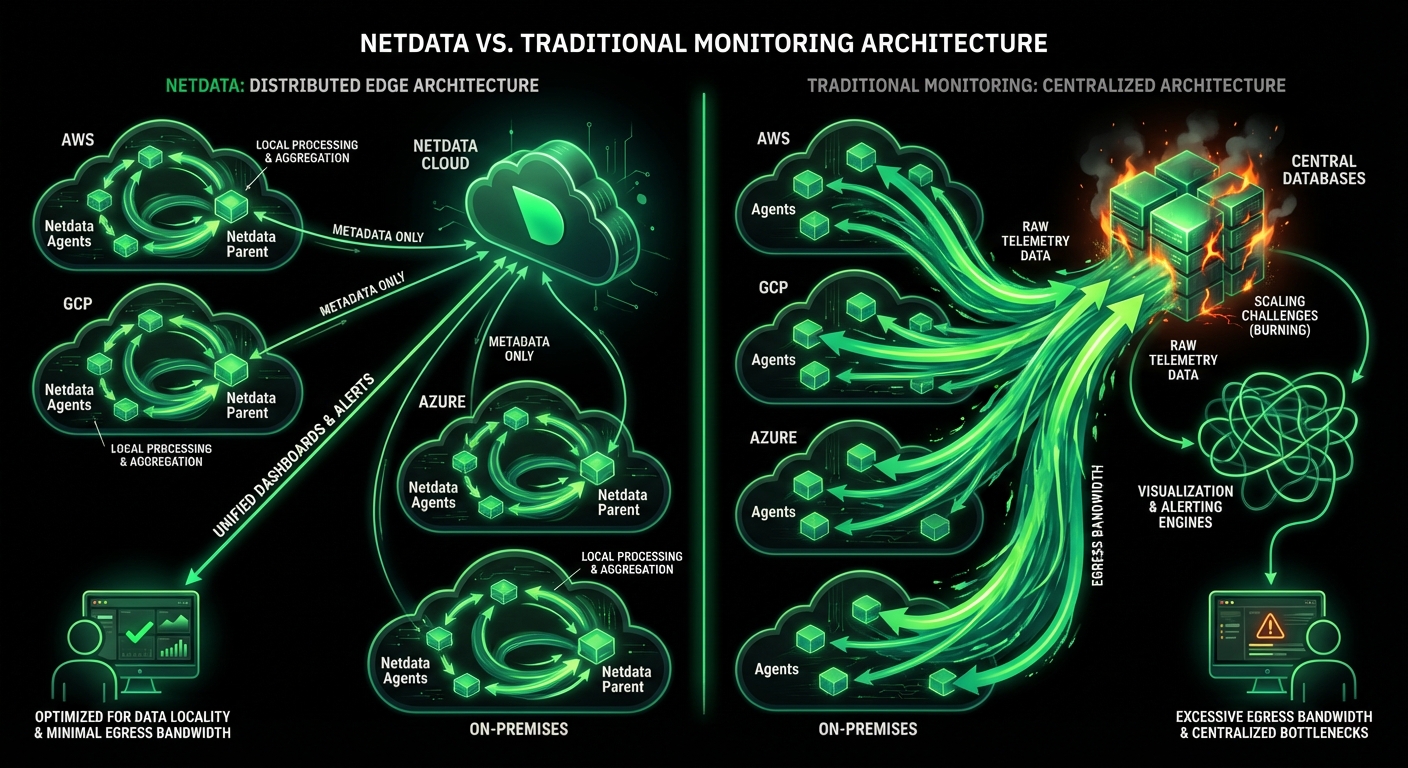

Scale Without Federation Complexity
Unlimited Scale
Learn About Scalability

Detect Anomalies with Unsupervised ML
99% false positive reduction
Discover ML Capabilities

Query Logs Without Pipelines
90% Cost Reduction
See Logs Management

Feature Comparison
Monitoring Features Side by Side
Comprehensive feature coverage comparison
Feature
Netdata
Prometheus
Operating System Monitoring
✅ Comprehensive
CPU, memory, disk, network, sensors
✅ Good
Via node_exporter
Container Monitoring
✅ Native
Docker, Kubernetes, cgroups direct
✅ Good
Via cAdvisor and exporters
Application Monitoring
✅ 800+ Integrations
Auto-discovery, zero config
✅ 100+ Exporters
Manual configuration required
Database Monitoring
✅ Advanced
MySQL, PostgreSQL, MongoDB, Redis
✅ Good
Via dedicated exporters
Network Device Monitoring
✅ SNMP Native
Auto-discovery and profiling
✅ SNMP Exporter
Manual MIB configuration
Hardware Monitoring
✅ Comprehensive
IPMI, sensors, GPUs, EDAC ECC
⚠️ Limited
Basic via exporters
Process Monitoring
✅ Live State
Real-time with history and ML
⚠️ Basic
Process exporter metrics only
Network Connections
✅ Per-Process
Live connections with bandwidth
❌ Not Available
No native support
Synthetic Checks
✅ Built-In
HTTP, TCP, DNS probing
✅ Blackbox Exporter
Separate component required
Custom Metrics
✅ Multiple Protocols
StatsD, OpenMetrics, OTel, REST
✅ OpenMetrics
Prometheus format required
Kubernetes Monitoring
✅ Native Operator
Pods, services, cluster metrics
✅ Native Operator
Industry standard integration
Cloud Provider Metrics
✅ AWS, Azure, GCP
Native API integration
✅ Via Exporters
CloudWatch, Stackdriver exporters
Key Netdata Capabilities
Anomaly Detection Without Configuration
18 unsupervised ML models train per metric at the edge, achieving 99% false positive reduction through consensus. No tuning, no thresholds, no expertise required.
Built-in intelligence
Learn About ML
Use Case Comparison
Netdata vs Prometheus Use Cases
Which platform excels for different monitoring scenarios
Use Case
Netdata
Prometheus
Real-Time Troubleshooting
✅ Ideal
Per-second visibility, console replacement
⚠️ Limited
15-30s delays miss transients
Infrastructure Monitoring
✅ Ideal
Comprehensive hardware, OS, network
✅ Good
Strong via node_exporter
Kubernetes Monitoring
✅ Advanced
Native operator, pod lifecycle
✅ Advanced
Industry standard integration
Capacity Planning
✅ Ideal
AI-powered forecasting, multi-tier retention
✅ Good
Historical queries, recording rules
Application Performance
✅ Good
OpenTelemetry tracing + process-level; no code profiling
⚠️ Limited
Metrics only, no APM
Multi-Cloud Monitoring
✅ Ideal
Unified view, edge-native
✅ Good
Via federation or Thanos
Edge/IoT Monitoring
✅ Ideal
Lightweight, works offline
⚠️ Challenging
Resource intensive for edge
Security Monitoring
✅ Good
Audit logs, anomaly detection
⚠️ Basic
Metrics only, no SIEM
Compliance Reporting
🔹 Data for your reports
SOC 2 Type 2; audit events and AI Insights reports for your own reporting
⚠️ Manual
Requires external tools
Cost Optimization
✅ Ideal
Predictable per-node pricing
⚠️ Complex
Hidden FTE and infrastructure costs

October 5, 2026
Distributed Tracing In Netdata: OpenTelemetry Traces
Netdata now ingests OpenTelemetry traces over OTLP on the same Agent that collects your metrics and logs. Spans are stored and indexed on your own infrastructure and explored in the new Traces tab in Netdata Cloud.

October 3, 2026
Who Built This Dashboard, and Are They Still Here?
Your server monitoring dashboard shouldn't be a DIY project. Netdata charts every metric automatically — no query languages, no dashboards to build, ever.
September 8, 2026
Infrastructure Knowledge For AI Root Cause Analysis
Netdata AI now learns your infrastructure the way a new SRE would: a shared context document your team writes, and a memory layer built from conversations that gets more accurate every time you use it.