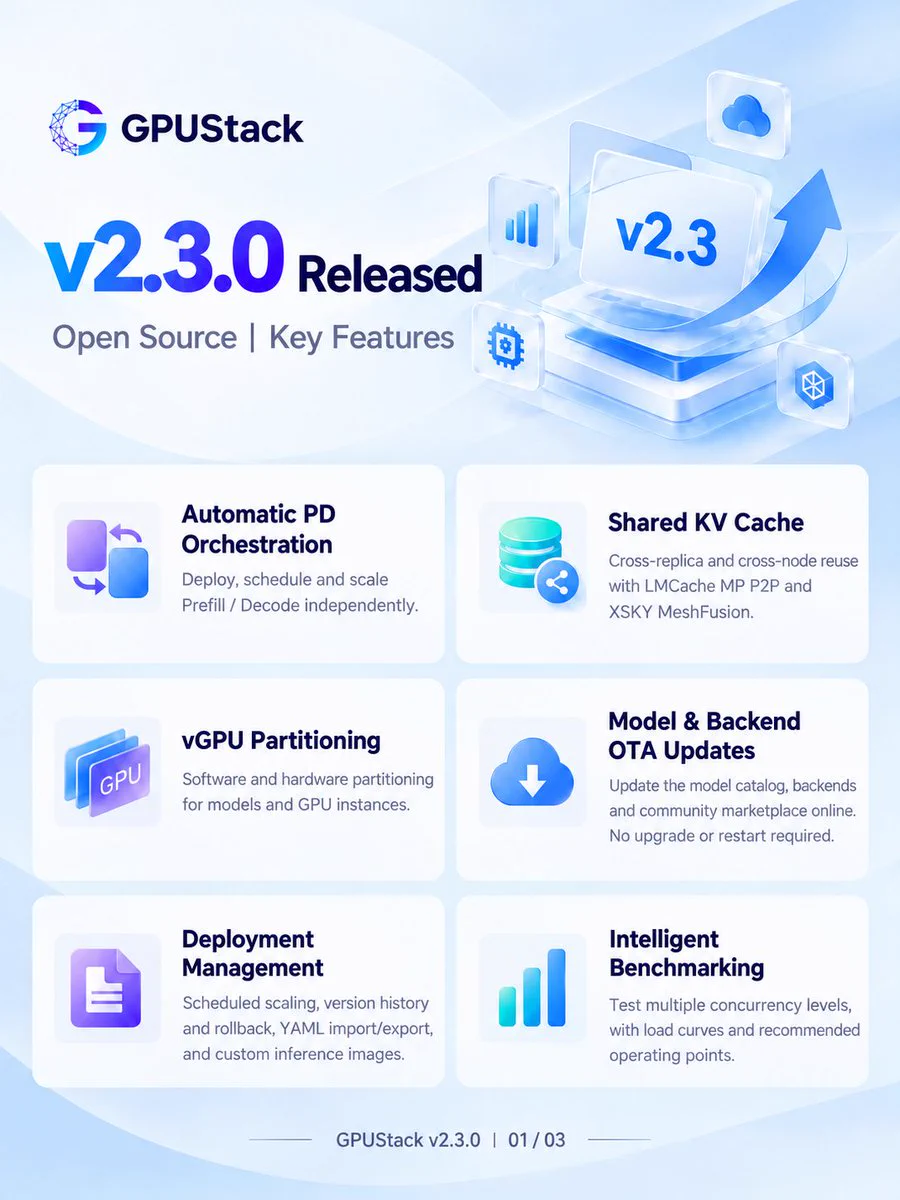
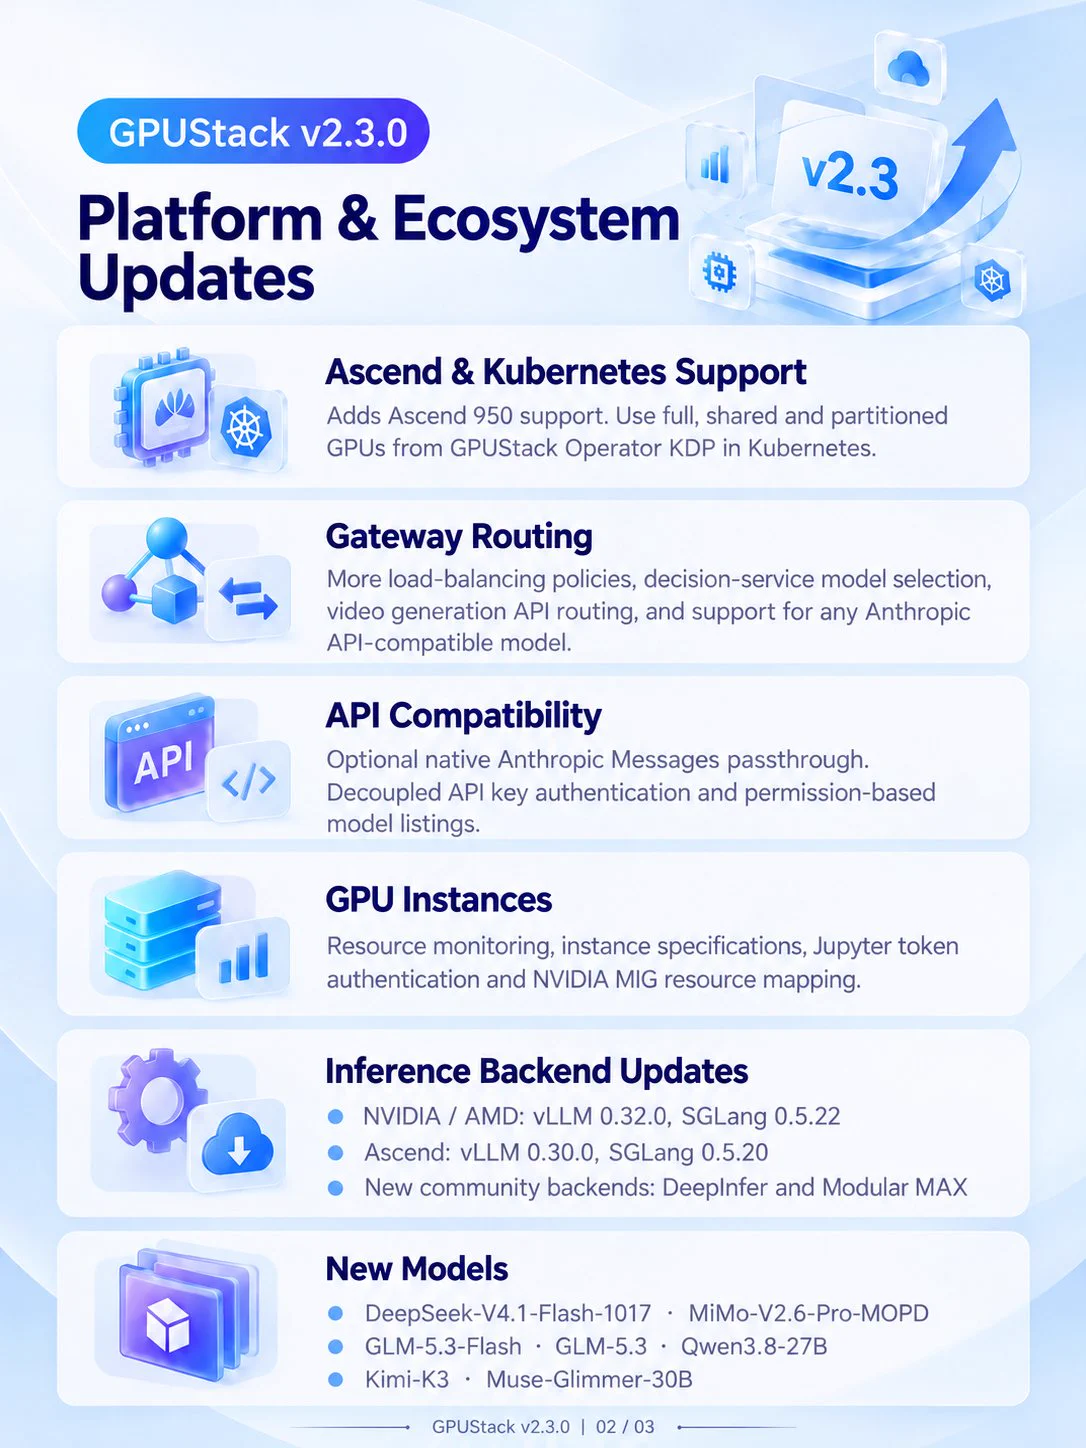
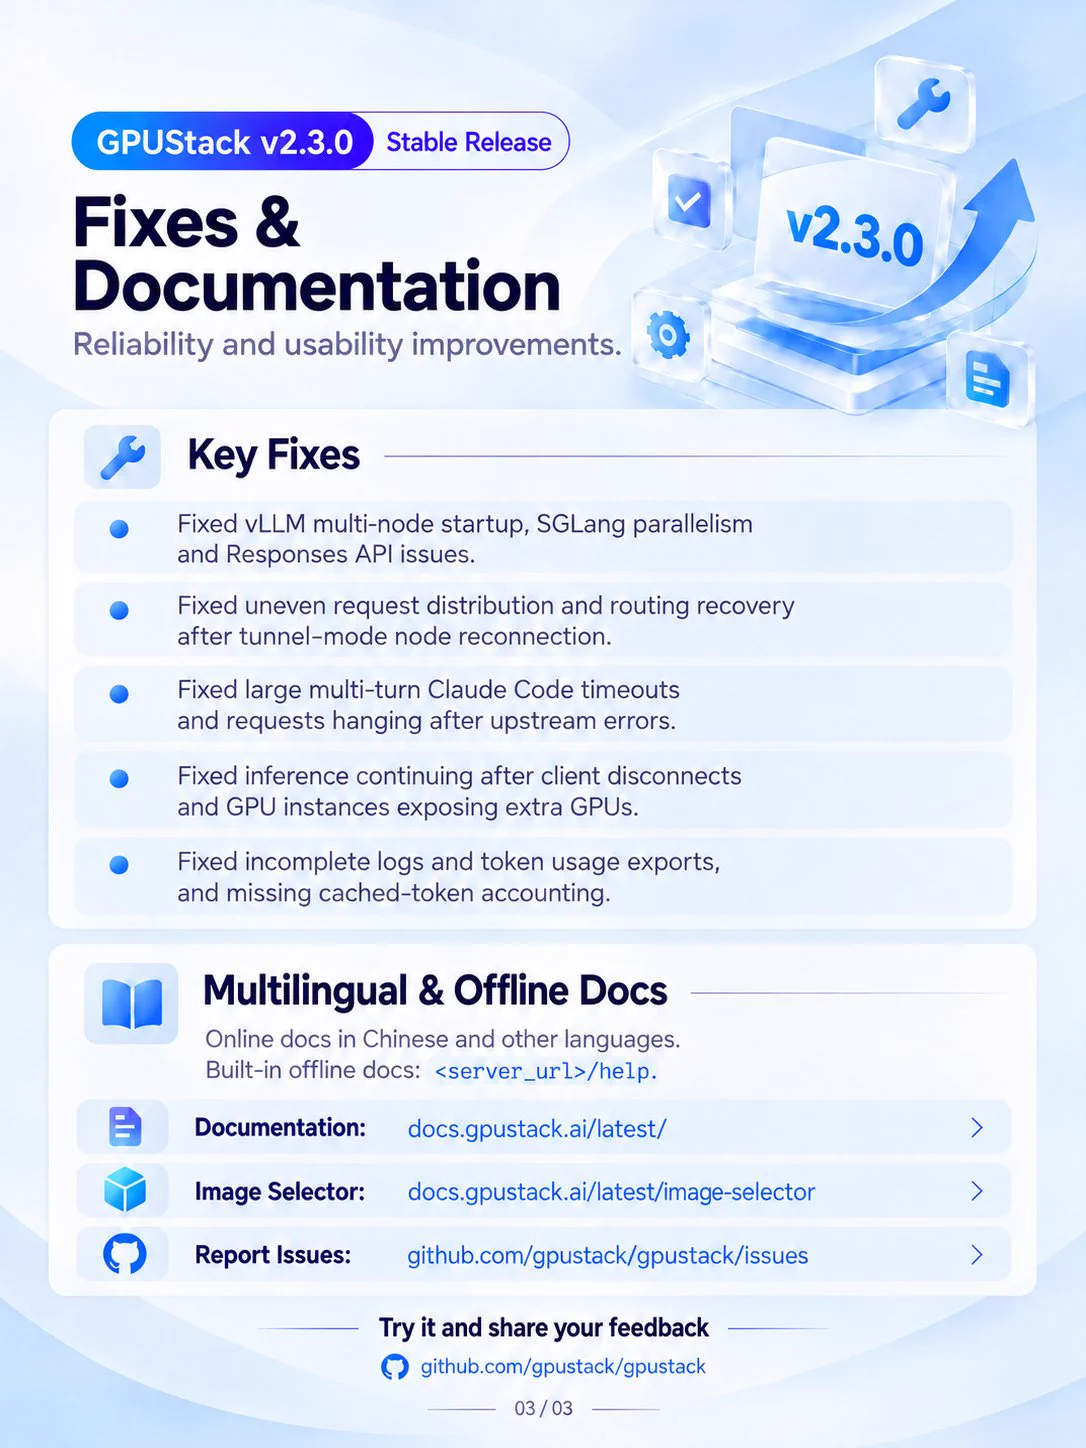
🎉 Congrats to @MiniMax_AI on the release of MiniMax-M3.1-Flash! 🚀 Day-0 support is here in GPUStack. Deploy it on your own GPUs, give it a try, and let us know how it works for you!
⭐ github.com/gpustack/gpust…
MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token.
Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and
“I’m faster.”
“At what?” 🦭
We brought @deepseek_ai’s DeepInfer to GPUStack and put it up against @vllm_project on 8× NVIDIA B200 GPUs.
In our 16-concurrent-request test, DeepInfer delivered ~25% higher average output throughput—but vLLM had lower time to first token and P95
DeepInfer meets GPUStack 🚀 On 8×B200, @deepseek_ai’s DeepInfer delivered 25.2% higher mean output throughput than @vllm_project, with longer time to first token.
Initial results; neither setup fully tuned.
GitHub: github.com/gpustack/DeepI…
Join us on Discord:
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more
🚀 DeepSeek-V4.1-Flash-1017 is now supported on GPUStack!
Get started with self-hosted DeepSeek on your own infrastructure, with full control over where your model runs. 🔒
👉 github.com/gpustack/gpust…
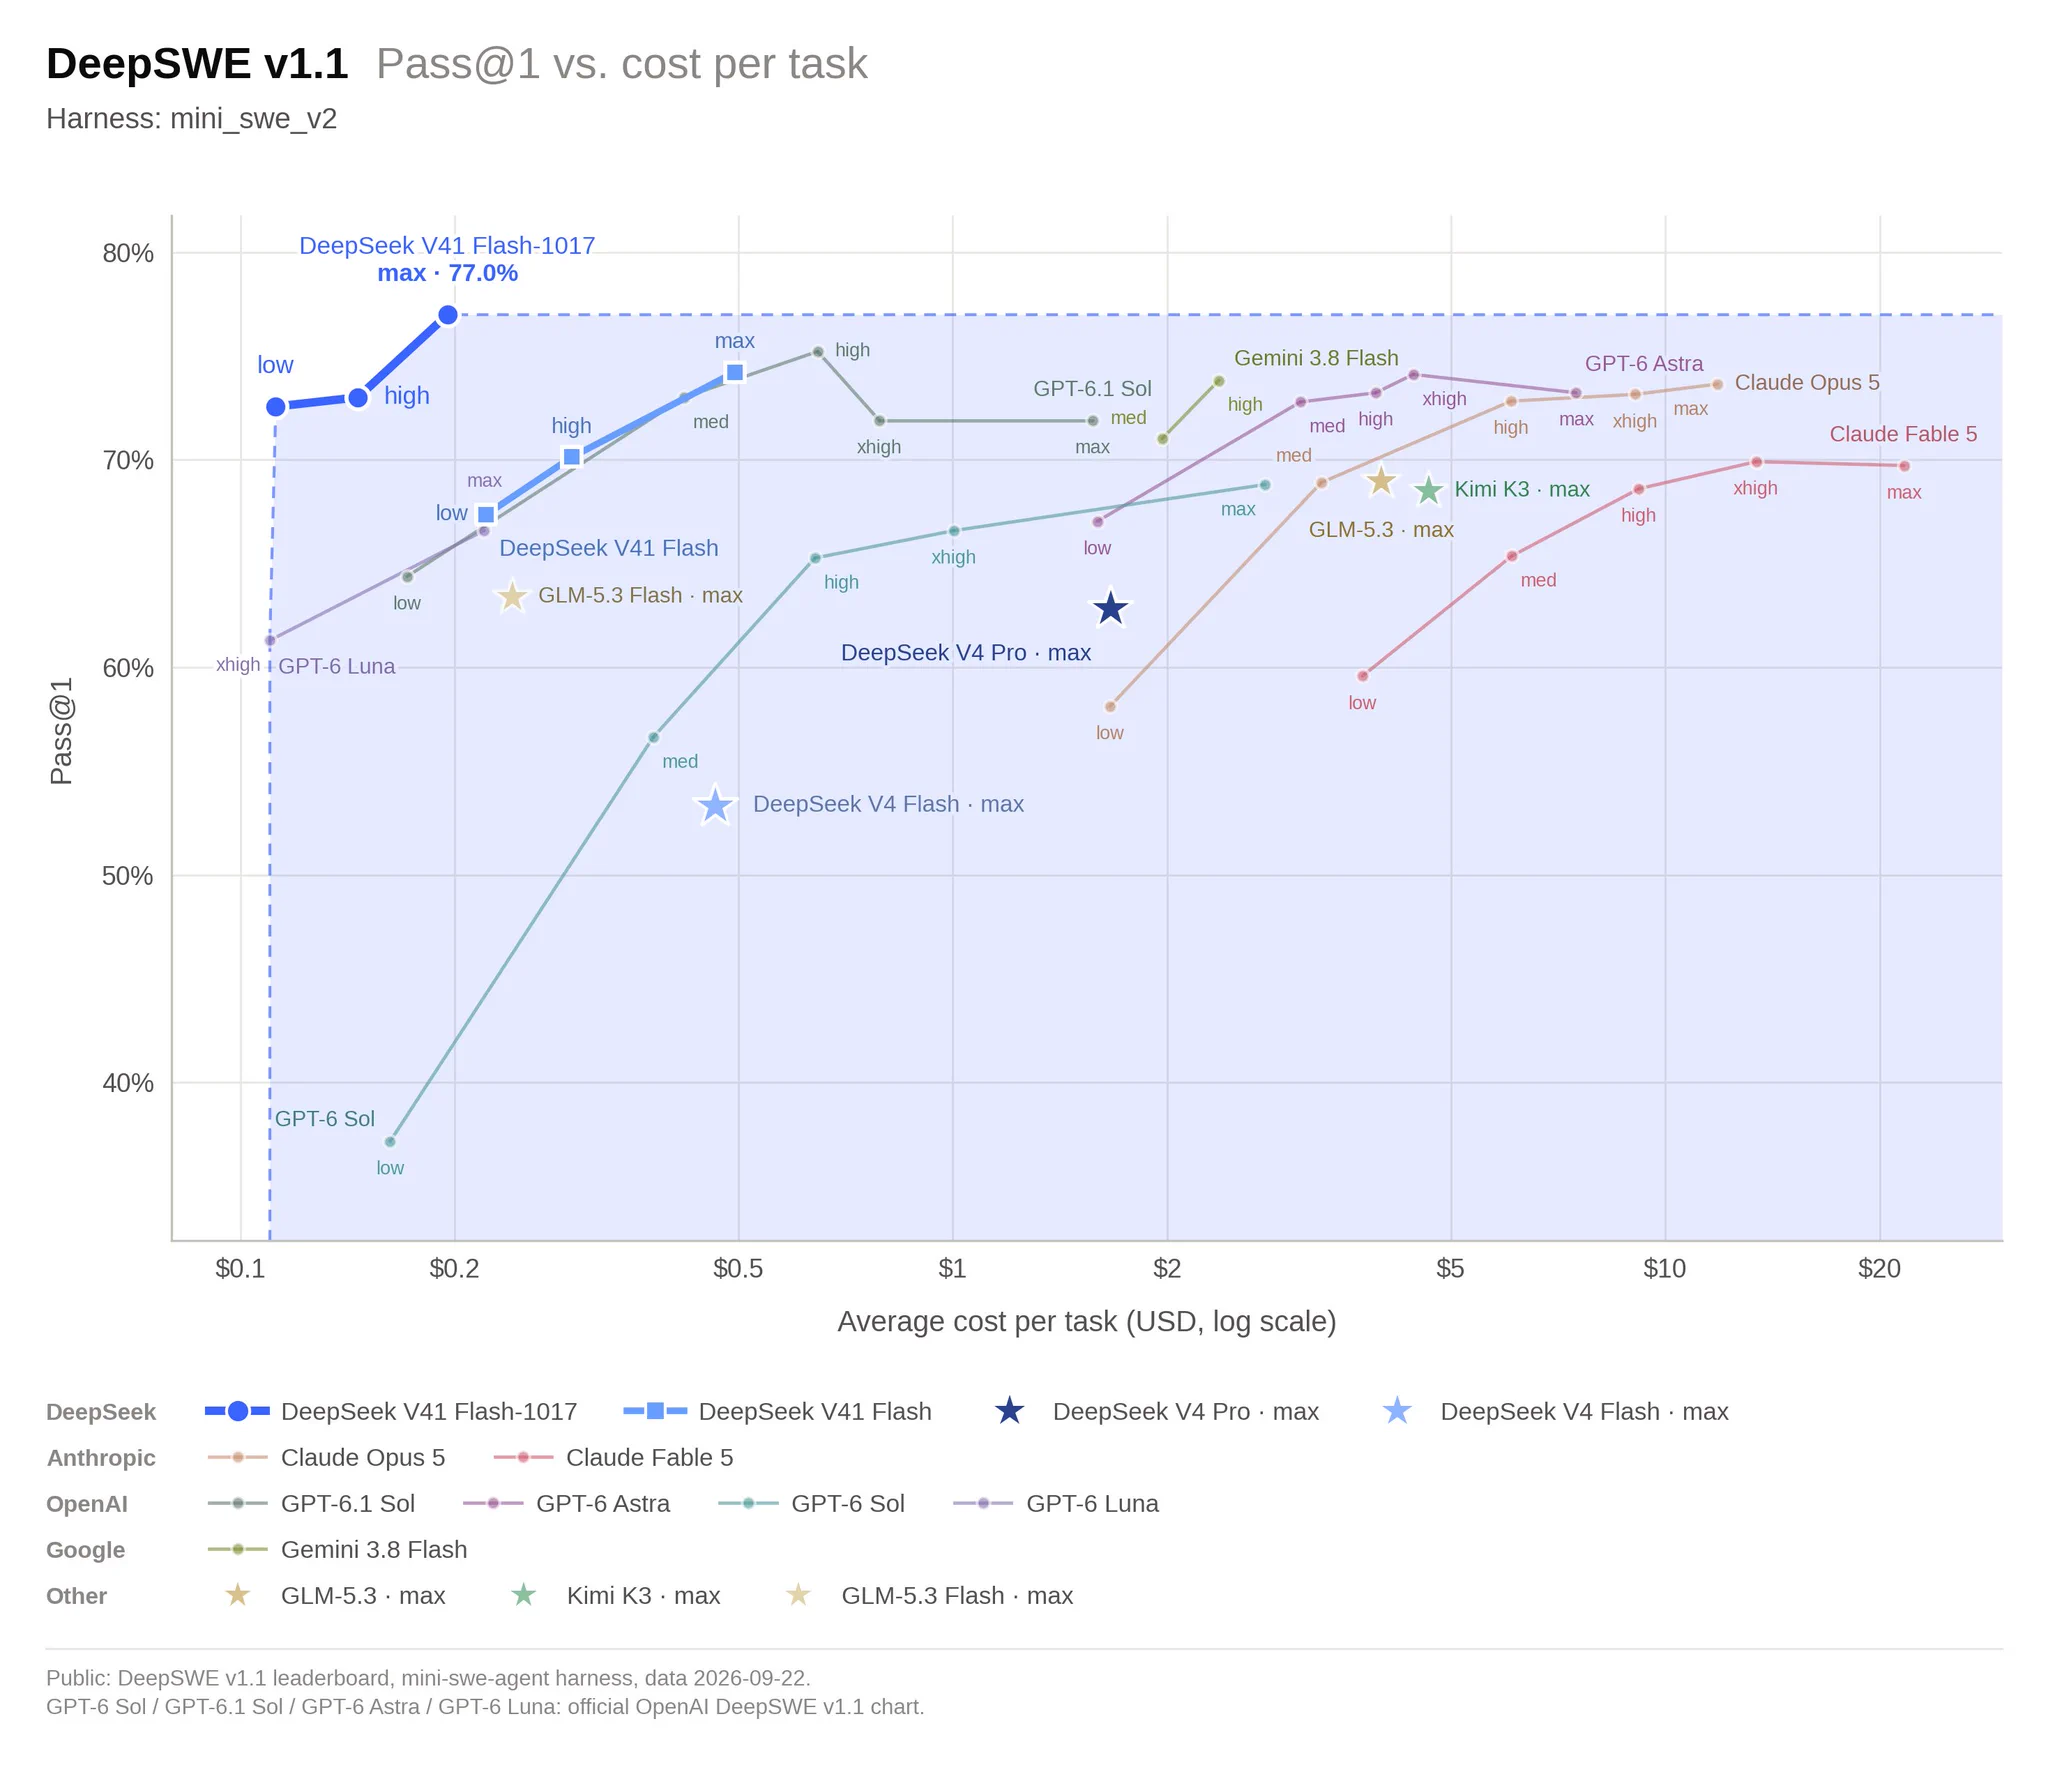
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy,