
Your AI has no idea what good looks like.
Your AI produces code that looks production-ready but doesn't conform to your standards. Invisible drift compounds with every release, costing you rework, refactoring, and velocity.
Trusted by over 4k+ companies

The Knapsack difference
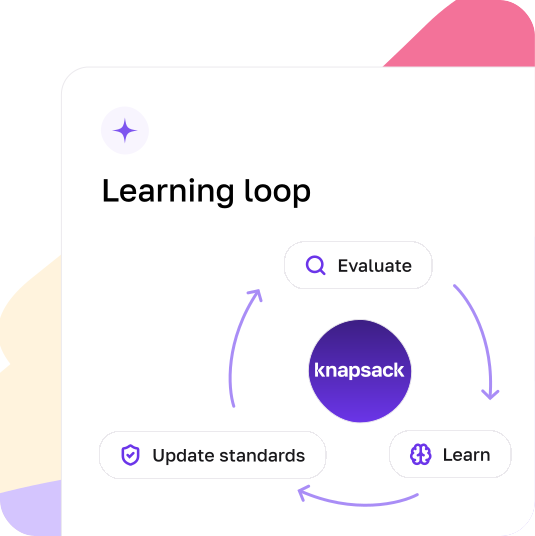
Anyone can put documents in a folder and point an LLM at it. The hard part is knowing which context to trust, measuring whether your AI's answer conforms to your standards, and proving it got better—not just faster. That is the whole product, and it is genuinely defensible.
Three Principles That Enable Evals
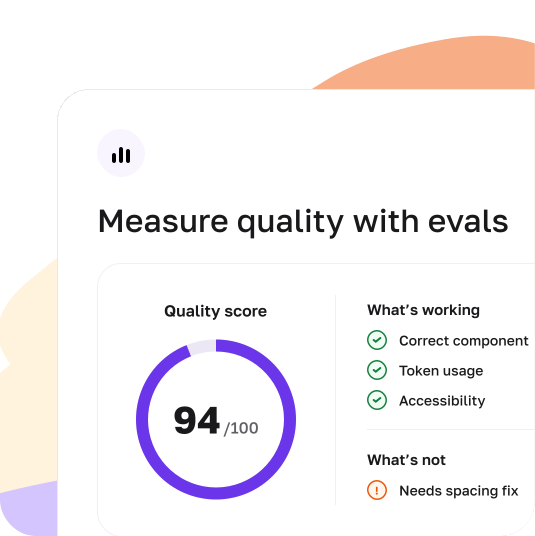
Measurement is the foundation. It reveals what's working, what's drifting, and what governance you need.
Provenance
Every evaluation starts with your source of truth. Your design system. Your patterns. Your decisions. We bring them together as-is, never rebuilt, never reinterpreted. We trace every conformance check back to what you own and control.
Analytics
You'll know if your AI is improving, where it's drifting, and what it costs to fix the drift. Design fidelity. Code quality. Cost per shippable output. Not just whether it works, whether it works for you.
Reliability
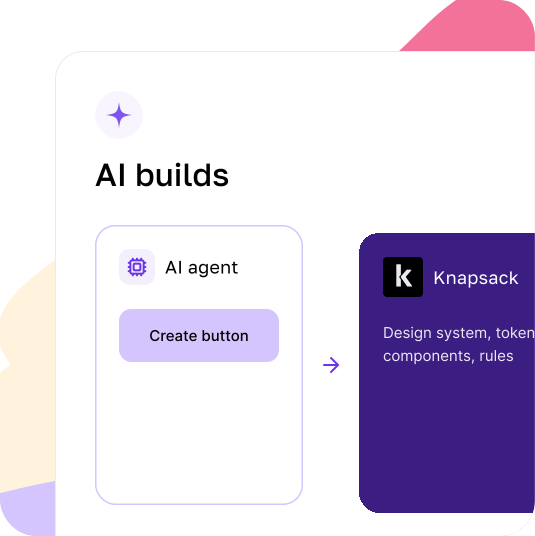
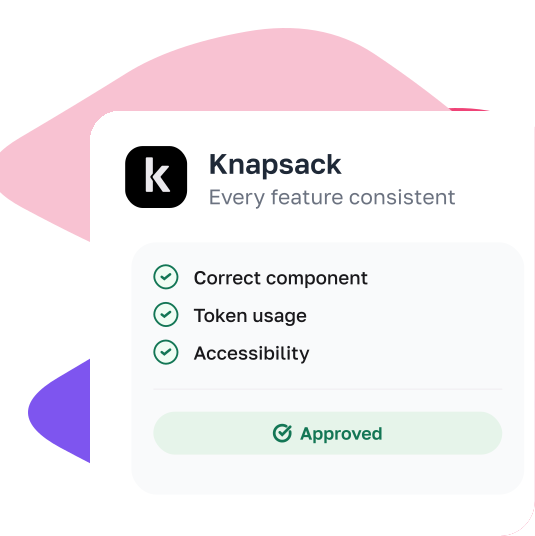
Governance isn't bolt-on. It's built in from the start. When your AI produces output, Knapsack checks it against your standards. That's what makes it safe to ship, not just fast to generate.
One source of truth for context, not scattered across tools
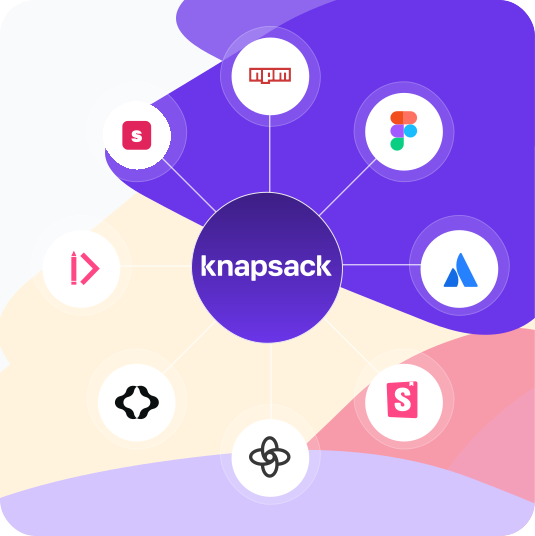
Your standards live across your tools—GitHub, Figma, Jira, Supernova, Storybook. Your AI needs them all to understand what good looks like. Knapsack brings them together as-is, without rebuild. Then we measure whether your AI conforms to what you've already decided.
How it works
Evals outcomes
60%
Less cost to land
a governed build
~7 in 10
drfited AI styling decisions detected
95%
Fewer invented
token names
100%
AI reached for the design system unprompted
Let’s get started
How much does your AI actually know?
Your product has standards. Your decisions matter. Take a quick assessment to discover how well your AI understands what 'good' looks like for your team.
Learn moreMeasure what matters, before you ship.
Design fidelity. Code quality. Conformance to your standards. Evals show you what's working and what's not—so you ship with confidence, not hope.
Join the waiting listWhere we learn together
Patterns is our thought leadership hub. Live demos. Workshops. Conversations about the future of AI context. It's where we show up for our community, and where you show up for us.