
A classifier takes a set of measurements and says which class it belongs to. Give it the height, weight and shoe size of a person and it can tell you which label that is in your training data.
You never write the rules yourself. The algorithm finds the boundary from the training data.
A classifier takes a set of measurements and says which class it belongs to. Give it the height, weight and shoe size of a person and it can tell you whether that is a male or a female label in your training data.
You never write the rules yourself. The algorithm finds the boundary from the training data.
Training data goes into the algorithm, it works out where the classes separate, and then you can predict with it.
Machine Learning Classification
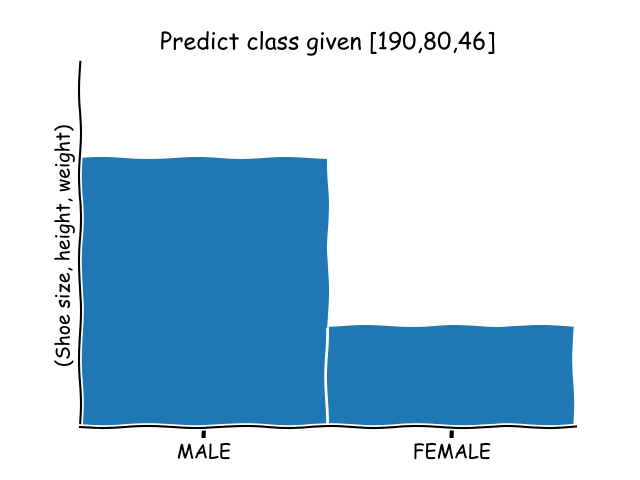
In the example below we predict if it’s a male or female given vector data.
We start with training data. In this example we have a set of vectors (height, weight, shoe size) and the class this vector belongs to:
Define a vector for your prediction in the same format (height, weight, size). If you want, you can also get this from console input:P = [[190,80,46]]
Then we fit the training data and predict in this style:c = Classifier()
c = c.fit(X,Y)
print "\nPrediction : " + str(c.predict(P))
That gives us this code:
How it learns
- You give it training data, one row of numbers per sample, plus the class for each row.
- You call
fit()and the algorithm works out where the classes separate. - You call
predict()with a new row and get the class back. - That separating surface is called the decision boundary.
- Accuracy is the share of predictions that were right.
score()gives it to you.
Different classifiers draw the boundary in different shapes. A decision tree draws steps, k-nearest neighbors follows the shape of the data and an SVM draws a straight line between the classes.
Want more practice on this? Practise this on PyChallenge, there are short browser exercises you can run right after reading.